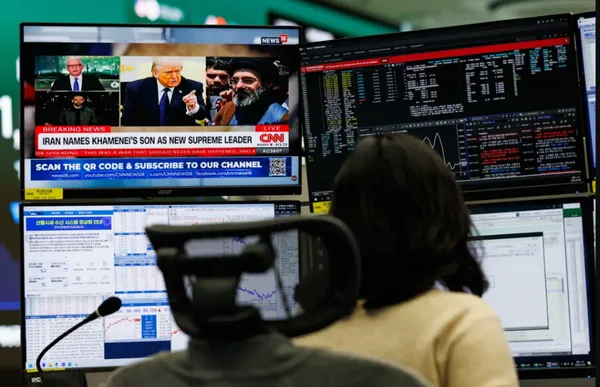
美股科技股暴跌,恐慌指数却岿然不动!BTIG警告:底部信号未现,抛售还没完

the lost malloc()
My favourite laptop
A Decade of Kill Bugs

Benchmarking: Qwen 27B, 35B, QFN180B; Nemotron Bolt 74B, Flint40B & Clover 35B (Q4) on M5 Max 2026 on Kapitsa with KFlash [P]
 | hey folks, I'm Ye, one of the contributors to Kapitsa, an open-source inference engine optimized specifically for Apple Silicon to run Qwen, Nemotron, Flint and Clover models locally. Our custom-written Metal kernels let us tune for each chip and each model. https://github.com/nace-ai/kapitsa/ The latest update, 0.2.26, is out. Since our last M5 Max numbers, Flash-Next 180B reads prompts 46% faster and the 27B writes 8% faster, and DiffuSpace's Clover 35B joins the catalog. Kapitsa also runs Qwen Flash-Next 180B with SSD offloading: on a Mac that can't hold it, the experts that don't fit in RAM stream from the SSD, so it runs on a 48 GB MacBook Pro at 61 tok/s. Here are the end-to-end numbers on a 2026 MacBook Pro 16 with an M5 Max and 128 GB: six targets (dense, MoE, hybrid Mamba-2 MoE and a block-diffusion MoE), from 1K context up to 32K, against the next-fastest engine for each. Try it (any Apple Silicon Mac; models in this post: ResultsDecode is a 512-token coding answer, prefill a 4K prompt, median of 3 runs:
From 1K context all the way up to 32K. At 32K the 35B still writes 175 tok/s, and Flash-Next barely drops (90 to 78): Against the other enginesAgainst the next-fastest engine for each model on the same Mac: 1.23x Splash on the 35B, 2.2x oMLX on Bolt, 1.18x rec on Flint and 1.12x mlx-serve on the 27B. Flash-Next is a tie with mlx-serve, Splash still reads prompts faster on the two Qwens, and nothing else runs Clover on a Mac. Every cell with versions and flags: benchmarks. Raw runs: results. Why it's fast: KFlashOther engines verify the drafter's guesses as one chain and stop at the first miss. KFlash verifies a best-first tree of the drafter's candidates in the same 8-row pass and keeps the longest branch the target agrees with. Three details make it fit Apple silicon:
Send us your benchmarksRun the same test on your Mac and add it to the community results. It takes 3-15 minutes: Plug in and close heavy apps while it runs. At the end it asks once: Enter sends the result as a pull request from your GitHub fork, and One more askDo you know prior work where tree-verified sampling matches plain sampling token for token under the same seed? Please point me to it so we credit it. We cite SpecInfer, Medusa, EAGLE-2 and Sequoia. [link] [comments] |
What actually broke when I tried to fine-tune on web-scraped data and what fixed it [D]
Fine tuning on self collected web data felt straightforward until it wasn’t. Here’s what actually caused problems:
Boilerplate contamination was the silent killer. Navigation menus, cookie banners, and footer text were leaking into training examples. The model started generating weirdly structured outputs that looked like half-rendered HTML. Solved it with aggressive DOM-targeting rather than raw text extraction and switching to a rotating residential proxy layer (per-request IP rotation means target sites serve you the same rendered DOM a real browser session would get, rather than a bot-filtered skeleton) made a noticeable difference in how clean the raw HTML was before I even touched the parser.
Deduplication order mattered more than I expected. Running exact dedup before fuzzy dedup produced meaningfully different training sets than the reverse. The model’s tendency to regurgitate phrasing shifted noticeably depending on the order.
The thing I still haven’t fully solved: near-duplicate detection across different languages. MinHash works fine monolingually, but multilingual dedup keeps surfacing edge cases I don’t love.
Curious whether others have hit the same issues, especially around multilingual corpora. Also genuinely wondering if anyone has a principled approach to deciding when scraped data quality is “good enough” to stop cleaning and just train.
[link] [comments]

Small-scale check of "good views beat next-token prediction" (Balestriero & LeCun 2026): human captions only, 11M-param encoders [P]
 | The paper claims text models align with image models faster when trained on "good views" (two different captions of one photo) than on bad views (one caption, words hidden) or next-token prediction. Its largest run used captions written by an image captioner, so image information could have leaked in. I tried a laptop-scale version with human captions only. Setup
Results (same learning speed, mean of 3 seeds)
Each method also got a small learning-rate search. Best speed, 1 seed: 0.328 / 0.196 / 0.168. Order unchanged. Limits
Code, chart and per-run results: https://github.com/IFAKA/platonic-lab What I would test next: does the gap shrink as the encoder grows? I could not test that on a laptop. Has anyone tried? [link] [comments] |
WTF Ubuntu?
In-N-Out may expand to these 3 states next, owner Lynsi Snyder says, as the 445-location burger chain pushes farther east
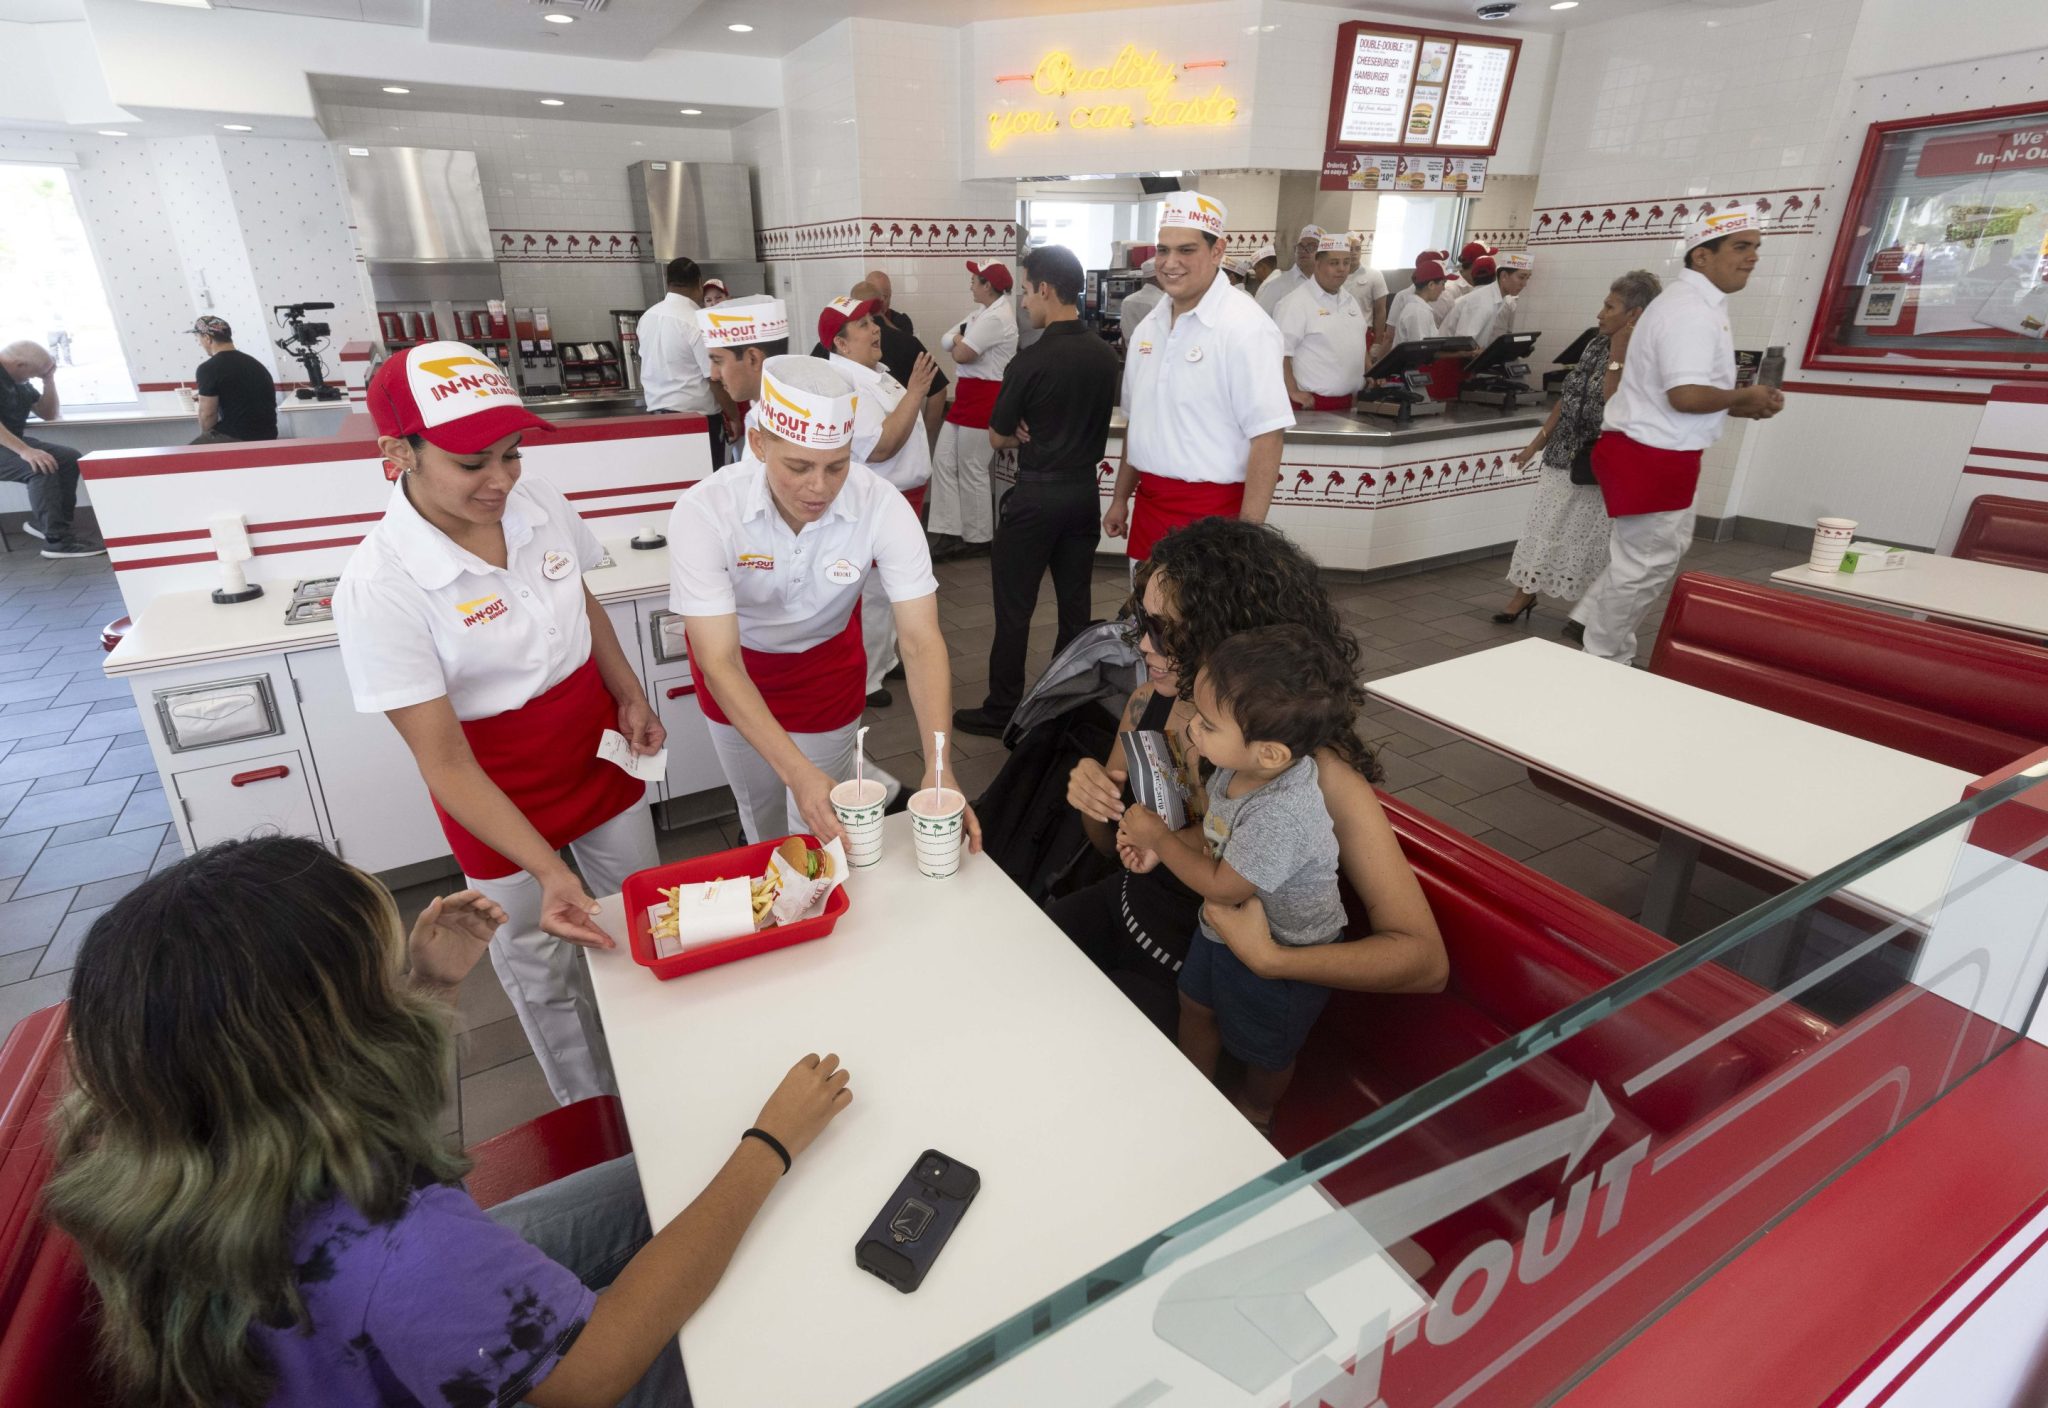
In-N-Out may be putting a little extra mustard on its expansion plans. The California-based burger chain is considering putting down palm tree roots in three new states—Arkansas, Mississippi, and Oklahoma—potentially expanding the pool of people who insist on explaining “Animal Style” to you.
The burger wars’ eastern theater: In-N-Out, which got its start just outside of Los Angeles in 1948, may be as synonymous with the West Coast as surfboards and clean IPAs, but:
- It has 445 restaurants in 10 states (including 289 in CA).
- It went farther east than ever last year, moving into Tennessee.
- It plans to open a New Mexico location next year.
Because the Tennessee In-N-Outs get supplies shipped from Texas, it could make sense to also open locations in Arkansas, Mississippi, and Oklahoma, since they’re already in the path of the distribution network, Lynsi Snyder, the chain’s owner and president, told actor Terry Crews in a dream we had an interview recently posted to the company’s website.
The chain also plans to expand in California.
Appetite for regional burger chains: In-N-Out saw domestic sales grow about 10% last year compared to 2024, trailing only New York-based Shake Shack among US burger chains, the Wall Street Journal reported in June, citing Technomic.—BC
This report was originally published by Morning Brew.
This story was originally featured on Fortune.com