European AI Office - Shaping Europe’s digital future

Union Types and Option Types

Benchmarking: Qwen 27B, 35B, QFN180B; Nemotron Bolt 74B, Flint40B & Clover 35B (Q4) on M5 Max 2026 on Kapitsa with KFlash [P]
 | hey folks, I'm Ye, one of the contributors to Kapitsa, an open-source inference engine optimized specifically for Apple Silicon to run Qwen, Nemotron, Flint and Clover models locally. Our custom-written Metal kernels let us tune for each chip and each model. https://github.com/nace-ai/kapitsa/ The latest update, 0.2.26, is out. Since our last M5 Max numbers, Flash-Next 180B reads prompts 46% faster and the 27B writes 8% faster, and DiffuSpace's Clover 35B joins the catalog. Kapitsa also runs Qwen Flash-Next 180B with SSD offloading: on a Mac that can't hold it, the experts that don't fit in RAM stream from the SSD, so it runs on a 48 GB MacBook Pro at 61 tok/s. Here are the end-to-end numbers on a 2026 MacBook Pro 16 with an M5 Max and 128 GB: six targets (dense, MoE, hybrid Mamba-2 MoE and a block-diffusion MoE), from 1K context up to 32K, against the next-fastest engine for each. Try it (any Apple Silicon Mac; models in this post: ResultsDecode is a 512-token coding answer, prefill a 4K prompt, median of 3 runs:
From 1K context all the way up to 32K. At 32K the 35B still writes 175 tok/s, and Flash-Next barely drops (90 to 78): Against the other enginesAgainst the next-fastest engine for each model on the same Mac: 1.23x Splash on the 35B, 2.2x oMLX on Bolt, 1.18x rec on Flint and 1.12x mlx-serve on the 27B. Flash-Next is a tie with mlx-serve, Splash still reads prompts faster on the two Qwens, and nothing else runs Clover on a Mac. Every cell with versions and flags: benchmarks. Raw runs: results. Why it's fast: KFlashOther engines verify the drafter's guesses as one chain and stop at the first miss. KFlash verifies a best-first tree of the drafter's candidates in the same 8-row pass and keeps the longest branch the target agrees with. Three details make it fit Apple silicon:
Send us your benchmarksRun the same test on your Mac and add it to the community results. It takes 3-15 minutes: Plug in and close heavy apps while it runs. At the end it asks once: Enter sends the result as a pull request from your GitHub fork, and One more askDo you know prior work where tree-verified sampling matches plain sampling token for token under the same seed? Please point me to it so we credit it. We cite SpecInfer, Medusa, EAGLE-2 and Sequoia. [link] [comments] |
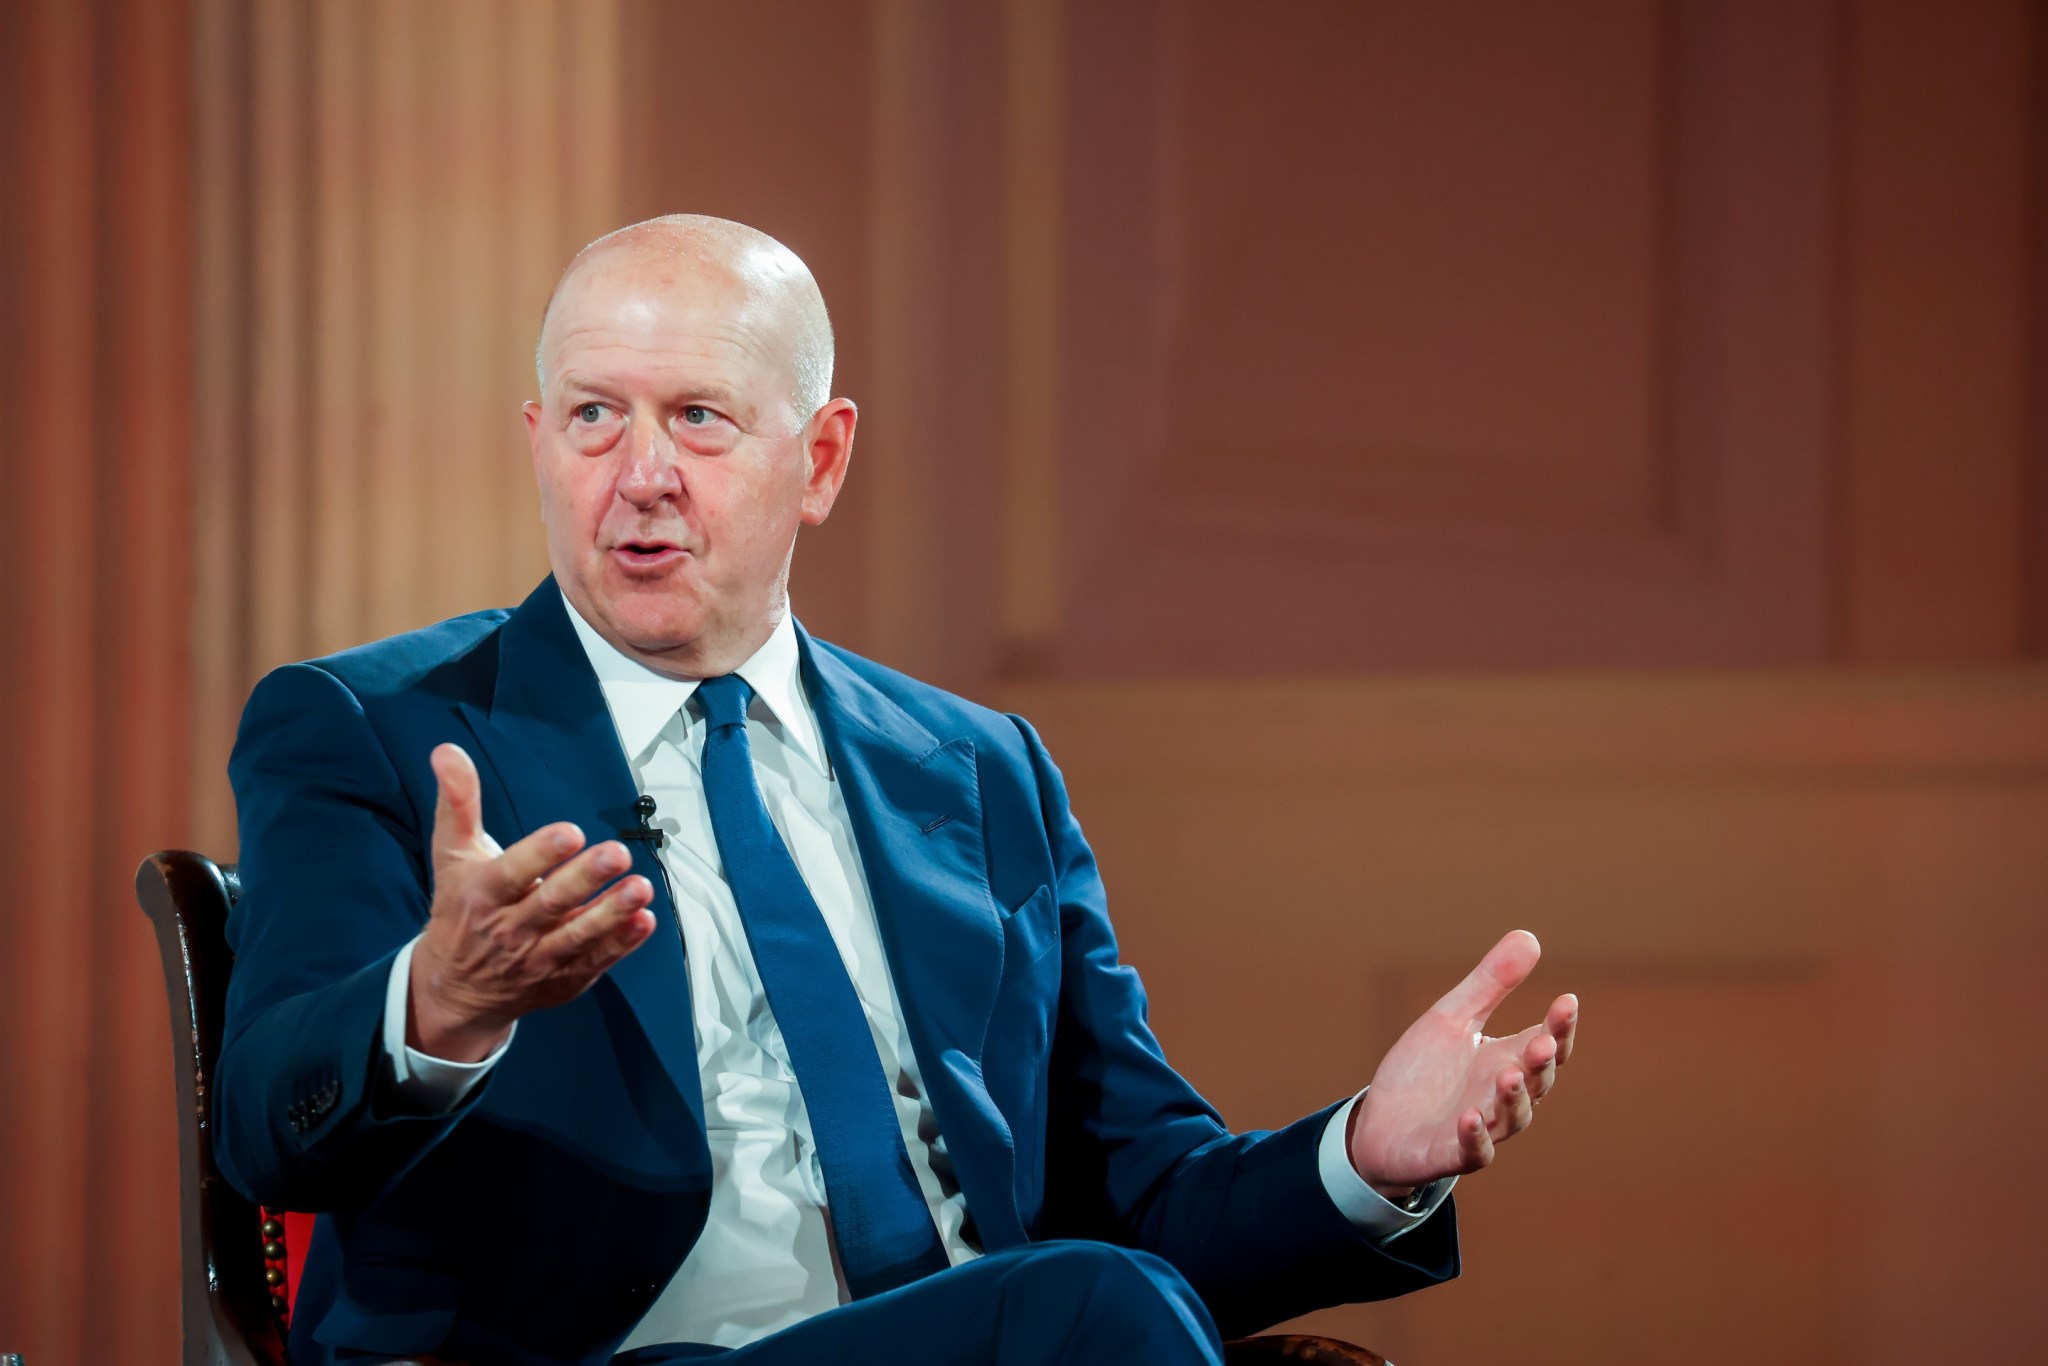
Goldman Sachs CEO David Solomon says the best advice he ever got came from his grandmother in his 20s: ‘Don’t be in a hurry’
David Solomon runs one of the most powerful banks on Wall Street, but the best career advice he ever received didn’t come from a mentor in a corner office. It came from his grandmother.
“Don’t be in a hurry,” the Goldman Sachs CEO told NBC News’ Christine Romans in a rapid-fire interview about his daily routine and the lessons that have shaped his career. He said she gave him that advice when he was in his twenties.
The clip came out of Romans’ wider conversation with Solomon for NBC’s Business in America series. That conversation aired Oct. 23, one day after Goldman launched its Small Business AI Institute, part of a new $500 million commitment to its 10,000 Small Businesses program, with Anthropic, Google, Meta, and OpenAI as partners. In the segment that ran on Nightly News, Solomon said he’s excited about what AI could mean for businesses and for people’s longevity.
In the lightning round, though, he talked less about markets and more about how he manages his days and his life.
Gym, coffee, and a protein shake before 7 a.m.
Asked to name three things he does before 7 a.m., Solomon kept it simple: He wakes up, goes to the gym, and generally has a cup of coffee and a protein shake.
He’s in good company. An early workout is a fixture of many executives’ routines, from the Bupa CEO who trains six days a week with his Gen Z son to the many leaders featured in Fortune’s Day in the Life of a CEO series.
The research suggests the habit matters more than the hour. A 2022 systematic review published in the Public Health Agency of Canada’s journal Health Promotion and Chronic Disease Prevention in Canada examined 35 studies. Eleven found morning activity more beneficial; 12 found afternoon or evening activity more beneficial; and 12 found no clear difference. The authors concluded there is no consistent evidence that exercising at one time of day is better for your health than another, and they rated the evidence quality as very low.
‘Stick to the schedule’
Solomon’s best trick for keeping his day on track is unglamorous: sticking to his schedule.
“The one thing that we can’t…get back is time,” he said, adding that he tries to be very purposeful with how he spends it. That means making commitments and keeping them, because, as he noted, it’s easy to drift off schedule.
The science backs him up, with a twist. A 2021 meta-analysis in PLOS One by Brad Aeon, Aïda Faber, and Alexandra Panaccio found that time management is positively linked to job performance. It was even more strongly linked to well-being, especially life satisfaction. In other words, the payoff from guarding your calendar may show up as much in how you feel as in what you get done.
Why slowing down isn’t a contradiction
At first glance, “stick to the schedule” and “don’t be in a hurry” seem to pull in opposite directions. For Solomon, they work on different timelines: Be disciplined with the hours in a day, and be patient with the arc of a career.
He repeats this message often. In August, he told Goldman’s summer interns at a town hall that taking more time can open up more opportunities, urging them to “try not to be in a hurry and enjoy the ride.” He offered small-business owners the same counsel about AI at the institute’s launch last week, telling them that “the important thing is to get it right, not to get it quicker.”
‘I don’t like to do things halfway’
Solomon’s patience has a limit, and it’s the things he cares about. Asked whether he has any obsessions, he said it depends on what has captured his interest.
“If I’m interested in something, I get very obsessive about it. I don’t like to do things halfway,” Solomon said. When something grabs him, he added, he tends to go deep.
Psychologists have found that kind of intensity cuts both ways. In a 2007 study in the Journal of Personality, Robert Vallerand and colleagues distinguished between “harmonious” passion, an activity you freely choose that fits with the rest of your life, and “obsessive” passion, which feels compulsive. Obsessive passion predicted deliberate practice and mastery-oriented goals, which supported performance. But it was also tied to fear-of-failure goals that undercut results. Harmonious passion delivered the upside with less of the downside.
The takeaway: Going deep can fuel success, as long as the obsession serves you, not the other way around.
Not every passion turns into a career, of course. Solomon also named one ambition he’s had to let go of: playing professional basketball. He conceded that one isn’t on the table.
This story was originally featured on Fortune.com
How Trump’s trade policy is handing Asia to Beijing
For a decade, Washington urged the world’s manufacturers to move their factories out of China and into friendly Southeast Asian states—only to attack the very countries and companies that answered the call.
Usually, U.S. economic statecraft is designed to help American companies succeed abroad. President Donald Trump’s punitive trade program is having the reverse effect. Broad-based import taxes have jolted manufacturers across ASEAN (the Association of Southeast Asian Nations), including American ones.
Rather than checking China, trade policy is alienating regional partners, harming supply-chain diversification, and eroding America’s influence over the bloc’s trade decisions. The U.S. is engaged in what Evan Feigenbaum, a veteran diplomat and former Republican, terms a “reverse pivot.” Bogged down in foreign crises elsewhere, Washington now projects hesitation and retreat in Asia rather than dynamic leadership.
In the months after President Trump’s April 2025 announcement of “Liberation Day” tariffs, some of ASEAN’s non-tariff barriers fell. A few countries used the exogenous threat to bring about needed reforms. Deals were done, including Boeing sales and–at least prospective–LNG contracts. It appeared that coercion worked, at least in the short term. In February the Supreme Court struck down much of the initial tariff regime and the administration pivoted to workarounds: 150-day emergency measures under Section 122 of the Trade Act of 1974, and expansive Section 301 investigations into forced labor, intellectual property violations, and “excess capacity.”
America’s labor, intellectual property, and excess-capacity concerns are really about China, not Southeast Asia. The administration substituted an improvised China policy for a coherent Southeast Asia policy—a strategic blunder. By treating regional partners as collateral damage to show that China isn’t singled out, Washington is undercutting its most reliable partners and allies.
Nowhere is the absurdity of this approach more evident than in the supply chains themselves. For nearly a decade, multinational corporations have redirected capital and manufacturing from China into Vietnam, Malaysia, India, and the Philippines. The goal of these “China plus one” strategies was to insulate critical industries from geopolitical risk and move them into friendly states.
Washington’s tariff regime now undercuts this strategy. Southeast Asian export hubs suffer far more than the United States when Chinese firms attempt illicit transshipment, while subsidized Chinese overcapacity squeezes local producers. The broader reality, though, is not widespread evasion but deep and legitimate supply-chain integration. By imposing blanket punitive duties, Washington is tightening the vise on the very partners helping achieve that diversification.
As Deborah Elms, head of trade policy at the Hinrich Foundation, has observed, Washington created the incentive structure for alternate supply routes and is now penalizing regional partners for using them.
These tariffs aren’t even achieving Trump’s stated goals. Higher costs and a shortage of skilled domestic labor mean production lines won’t magically shift to U.S. shores. Bilateral trade deficits with Southeast Asian economies remain largely unchanged; regional exporters, U.S. importers, and consumers are simply absorbing higher costs.
ASEAN nations have long been masters of dynamic hedging—exemplified by Vietnam’s “bamboo diplomacy”—balancing China against the United States. None of them want to be dominated by Beijing, making Washington their natural partner. Yet as U.S. policy grows increasingly erratic and punitive, it inadvertently pushes them to hedge elsewhere.
As Canadian Prime Minister Mark Carney warned at the World Economic Forum in Davos in January, the weaponization of economic tools forces middle powers to organize: “If we are not at the table, we are on the menu.”
Coercive tactics failed with Canada, and they will fail in Asia. Recently, politically appointed U.S. ambassador to Singapore Anjani Sinha told local and international business leaders that he received orders from the President to “bring home the money,” so they needed to double their U.S. investments. The demand went over like a lead balloon. Capital flows are not surging into the United States; they are pivoting further into Asia.
This friction runs counter to decades of bipartisan precedent. Since the 1985 Plaza Accord, which catalyzed an era of industrial integration in Southeast Asia, American leaders have recognized that regional partners thrive under predictable, rules-based frameworks rather than blunt coercion. Today’s transactional posture risks creating a durable trust deficit that will penalize American enterprise for a generation.
Since America pulled out of the Trans-Pacific Partnership in favor of country-by-country negotiations, its absence at the table has been filled by others. ASEAN is now building institutional networks that bypass Washington altogether. Member states are working with accords like the Regional Comprehensive Economic Partnership (RCEP) and the Comprehensive and Progressive Agreement for Trans-Pacific Partnership (CPTPP).
American companies have not forgotten the benefits of clear rules of the road in a multilateral context. They have worked closely with ASEAN negotiators toward the ASEAN Digital Economy Framework Agreement (DEFA). Spanning 11 nations, nearly 700 million consumers, and an estimated $2 trillion digital marketplace, DEFA would establish comprehensive standards for cross-border data governance, cybersecurity, digital identity, and artificial intelligence.
As Washington retreats behind tariffs and procedural disputes, Southeast Asia—with input from U.S. companies—is writing the regulatory architecture of the 21st-century digital economy.
Washington builds walls while ASEAN builds architecture.
Southeast Asia does not wish to decouple from the United States. Four ASEAN nations—Vietnam, Thailand, Mal

Fears over $828 billion AI capex spending spree help erase $1 trillion in market value
The richest companies in the history of the world are spending so much on the infrastructure backing AI that they’re burning through billions in cash and threatening a recent AI-fueled stock surge as Wall Street wavers.
The latest financial disclosures by four of the biggest hyperscalers, Amazon, Alphabet, Microsoft, and Meta, as well as Elon Musk’s up-and-coming AI player, SpaceX, which includes xAI, revealed that the small group of tech heavyweights is set to invest as much as $828 billion on capital expenditures this year. That spending includes data centers, high-powered chips, and other infrastructure that fuels AI.
Making up the $828 billion in capex spending is an expected spend for 2026 of $220 billion from Amazon, up to $205 billion from Alphabet, approximately $170 billion from Microsoft, up to $145 billion from Meta, and up to $88 billion from SpaceX, according to company earnings releases and calls.
At this point, the massive AI infrastructure bill has surpassed the market value of well-known businesses like energy giant ExxonMobil or payments company Mastercard and is even approaching the roughly $1 trillion America is spending on defense this fiscal year, itself the largest in the world. Several banks, including Evercore and Bank of America, see capital expenditure related to AI hitting $1 trillion in 2027.
Partly in response to this massive spending, stocks tumbled on Friday, leading both the Nasdaq and the S&P 500 to their worst one-day performances since June. The tech-heavy Nasdaq closed down 2.9%, while the S&P 500 fell 1.8%. Nasdaq 100 companies lost more than $1 trillion in market value. Sour guidance for the last three months of the year from U.S. chipmaker Intel also played a role.
Some of the market’s jitters can be drawn to concerns over free cash flow, which has long been a source of strength for Silicon Valley companies but has recently taken a turn. Four of the five tech giants spending hundreds of billions cumulatively on capex had negative free cash flow in the third quarter (Microsoft was the exception), meaning they spent more on buildings, equipment, and other capital investments than they generated in cash from their operations.
As companies that built their fortunes selling software and services increasingly pour money into physical infrastructure they are looking to borrow or raise more in some cases to pay for it. With a handful of technology stocks accounting for an outsized share of the S&P 500, the success or failure of these companies’ investments could have enormous implications for the market and the millions of Americans invested in it.
Aleksandar Tomic, an economist and the associate dean at Boston College, warned that these infrastructure investments could lead to consequences far beyond Silicon Valley if they don’t pan out, especially as companies increasingly rely on debt to finance their expansion. This increased borrowing could raise the cost of capital for other businesses, while a downturn among the tech giants could ripple throughout the broader economy.
“If these tech companies sneeze, the rest of the market would catch pneumonia,” Tomic told Fortune.
A costly bet
Microsoft’s recent financials show how keeping up in the AI race is affecting tech companies’ decisions overall.
For decades, the software giant has been one of the world’s biggest cash-generating businesses. It earned nearly $134 billion in profit during its latest fiscal year and generated almost $183 billion in cash from operations. Still, during the same period, its cash spending on property and equipment rose about 80%.
Microsoft announced a $25 billion bond offering Thursday, its first bond sale in more than nine years. The company said it would use the money for general corporate purposes, which it said could include capital expenditures.
Microsoft remained free cash flow positive last quarter unlike competitors, Amazon, Alphabet, Meta, and SpaceX, but as the costs of infrastructure increase, the company is looking to raise funds.
Meta reported negative free cash flow of $2.1 billion last quarter, compared with positive $10.6 billion during the same period a year earlier. On Monday, it announced it would issue new shares in a plan to raise up to $95 billion that will give it more funds it could put toward AI infrastructure.
Oracle, another major player in the AI infrastructure race, is also relying on borrowing and other avenues to support its expansion. The company told investors this week that it doesn’t expect to return to positive free cash flow until the second half of its next fiscal year, which would run from the six months prior to May 2028. After that, the company said, it predicts free cash flow shooting up to at least $30 billion for the fiscal year ending in May 2029.
The AI payoff
For now, some big tech companies can point to the encouraging sign that demand for computing power is translating into record cloud revenue. Google’s cloud revenue more than doubled last quarter to $30.7 billion, while Microsoft’s Azure business grew 48% to approximately $33.3 billion and Amazon Web Services expanded 39.3% to $46 billion. Despite its slower growth rate, AWS remains the largest of the three by quarterly revenue.
Cloud providers make money partly by renting compute to AI providers. As AI demand is also projected to grow in the coming years, these operations could be a welcome source of revenue for hyperscalers. Still, not all cloud revenue comes from AI, and rising sales don’t necessarily validate the giant investments of today.
In other positive news for the AI sector, Claude maker Anthropic filed paperwork for an initial public offering this week, helping to boost the Nasdaq 0.8% on Monday. The filing also drew attention to more than $265 billion i
‘Fastest entertainment property in history’: GTA VI arrives to test a thin November box office
A nearly three-hour documentary about Elizabeth Holmes was the No. 1 movie in America over Halloween weekend. That’s a triumph for A24, and a scary harbinger for theaters heading into a thin November that faces competition from an entirely different corner of entertainment.
A24’s You Can See Everything, directed by Nathan Fielder and Lance Oppenheim, took in $11.4 million in its third weekend, narrowly edging DC Studios’ Clayface, according to Monday’s final figures reported by Variety. It had finished second in each of its first two weekends, behind Street Fighter and then Clayface. Its domestic total now stands at $64.7 million.
It is the first documentary outside the concert genre to top the box office since Michael Moore’s Fahrenheit 9/11 in 2004. But its lack of direct competition is telling. No studio opened a wide release, and overall ticket sales came to about $56 million, down more than 40% from the prior weekend and the second-lowest total of the year, according to studio estimates.
Why Halloween weekends sink the box office
Unlike Christmas, Thanksgiving, or the Fourth of July, Halloween doesn’t boost the box office when it lands on a weekend. People don’t get an extra day off, and they’re more likely to spend peak moviegoing hours trick-or-treating or at parties.
The last Saturday Halloween, in 2020, came while most theaters were shuttered. The one before that, in 2015, was the weakest weekend of that year to that point: three new wide releases flopped, and The Martian stayed on top in its fifth week, as Fortune reported.
A thin November slate
This year’s quiet Halloween also foreshadows a challenging month. The biggest swing is Lionsgate’s The Hunger Games: Sunrise on the Reaping on Nov. 20, the sixth film in the franchise and an adaptation of Suzanne Collins’ 2025 bestseller. Boxoffice Pro’s long-range tracking puts its opening at $55 million to $65 million; the last installment, 2023’s The Hunger Games: The Ballad of Songbirds & Snakes, opened to $44.6 million.
Thanksgiving week brings Disney’s animated Hexed and Universal’s Focker In-Law, both on Nov. 25. Focker In-Law is a greater gamble: the fourth film in the franchise that began with 2000’s Meet the Parents arrives 16 years after Little Fockers, which opened to $30.8 million in 2010.
Warner Bros.’ animated The Cat in the Hat and Searchlight’s Wild Horse Nine open Nov. 6, and smaller titles like Ebenezer: A Christmas Carol and I Play Rocky are sprinkled through the month. But the box office’s most likely competition comes from the video game business: Rockstar Games releases Grand Theft Auto VI on Nov. 19, one day before Sunrise on the Reaping opens.
The month’s biggest launch isn’t a movie
The sixth game in the series arrives 13 years after Grand Theft Auto V, and anticipation has been building for years. Rockstar confirmed development in February 2022; that September, a hack leaked roughly 90 clips of early footage, and in December 2023 the first trailer leaked hours before its scheduled debut. The game promises a more expansive setting than any previous Grand Theft Auto title.
Grand Theft Auto V generated $800 million in sales in its first 24 hours in 2013 and passed $1 billion in three days, which publisher Take-Two Interactive called the fastest any entertainment property had reached that mark. It has since sold more than 230 million units, according to Take-Two’s August 2026 earnings report.
GTA VI is poised to beat those numbers. Analytics firm Sensor Tower estimates it had drawn 6.45 million digital pre-orders worth about $630 million as of Oct. 20, excluding physical copies. That global, pre-launch haul already tops the roughly $625 million domestic run of Christopher Nolan’s The Odyssey, the year’s second-highest-grossing film behind Spider-Man: Brand New Day.
It is also more than 11 times what every movie in North American theaters grossed over Halloween weekend. For Take-Two, which reported $6.66 billion in revenue in its fiscal year ended in March, the launch underpins a forecast of $8 billion to $8.2 billion in net bookings this fiscal year.
Video games may draw a narrower audience than theatrical films, but a release this size is bound to occupy the attention of millions later this month. That’s likely to pull some of them away from the big screen for at least a weekend, leaving a notable dent in the fall box office.
This story was originally featured on Fortune.com
You can't make an omelette without breaking some urns
TL;DR In this post, we investigate two methods that aim to improve training efficiency over standard PPO for a grid world RL agent. In our experiments these methods can converge on better policies, but take roughly twice as long to do so. This project was done in the context of an ARENA 8.0 capstone project. Our code is available on GitHub.
Introduction
Reinforcement learning agents are trained to maximise a given reward function in their training environments. Common failure modes of the training process are reward hacking and goal misgeneralisation, roughly corresponding to outer and inner misalignment respectively.
Reward hacking occurs when the supplied reward function does not correspond exactly to the developer’s intent, and the agent learns a way to satisfy the reward function without satisfying the intended objective. This can be addressed, at least in principle, by designing a better reward function.
Goal misgeneralisation can occur even with a perfect reward function. If training and deployment environments differ, policies that satisfy the reward function during training, might fail to do so during deployment. Such policies are indistinguishable during training and we cannot control which one the agent learns.
If the distribution of deployment environments is entirely disjoint from the training distribution, goal misgeneralisation is inevitable. Consider, for example, training an agent to collect green apples while avoiding red boxes. What would happen if it gets deployed in an environment with red apples and green boxes? The behaviour is undefined. (It is also unclear what the intended behaviour would be in this case.)
Goal misgeneralisation is likely if deployment environments are not contained in the training distribution. But even if they are, correct generalisation cannot be guaranteed. In this post we present a case study and investigate two mitigations.
The pottery shop environment
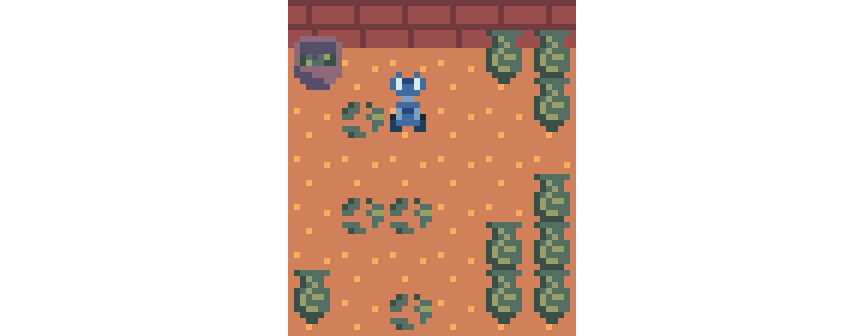
Our object of study is the pottery shop environment.[1] It is a grid world environment containing the agent, a bin and one or more urns and (piles of) shards. The agent can pick up and carry one shard at a time. Its task is to collect all shards and drop them into the bin as quickly as possible. If it steps on an urn, the urn breaks and creates a new pile of shards to clean up.
An example level of the pottery shop environment (on a grid)
Interesting behaviour occurs when urns are on the direct path between the agent and the shards or the bin. The intended optimal policy is to walk around the urns if that path is only slightly longer. But if the detour gets too long, the agent should break some urns, creating a shortcut.[2] The cost of breaking the urns is lower than the cost of taking the detour. For computational efficiency, we limit our investigations to environments of size and .
We use the following reward function, which ensures that this is indeed the optimal policy.
- Dropping a shard in the bin gives reward +1
- Breaking an urn gives a penalty of -3
- We add a reward shaping term , where and are the states before and after the action. And the potential is 1 if the agent is holding a shard and 0 otherwise. This term encourages the agent to pick up shards as an instrumental goal without incentivising reward hacking by repeatedly picking up and dropping the shard.
- Finally, we add a step cost that is incurred at every action, as long as there are still shards to clean up. This is the crucial term that makes shortcut creation optimal by penalising long detours. Note that the discount factor alone does not penalise detours sufficiently. We set the step penalty to 0.2 and 0.02 in and environments respectively.
We use a discounting factor .
Our training environments are randomly generated as follows. The number of shards and urns is sampled randomly from a geometric distribution. The agent, urns and shards are then randomly placed on the grid. Sampling from a geometric distribution ensures that any number of urns and shards is possible, but higher numbers (i.e. dense levels) are less common. Every possible environment is thus accessible during training, but the distribution is heavily biased towards sparse levels. In particular, this means that it is rare to generate levels with long walls of urns, i.e. those where the optimal policy is to create a shortcut. Given the total length of training, the agent will nevertheless encounter a significant amount of them. The deployment distribution is a small set of hand-crafted levels, containing urn walls of various lengths. Across all environments, we fix the bin position to the top left corner.
We expect the agent to learn to always walk around walls, because that is the optimal policy in almost all of the training environments. In the deployment distribution, it should behave competently, but miss out on the opportunity to break walls and achieve optimal reward.
PPO to the rescue
We start with standard proximal policy optimisation (PPO). PPO training consists of two phases:
- Rollout phase. We generate random levels, rollout the policy (without updating weights) and collect transitions into memory.
- Training phase. We then train on batches of transitions and update the agent’s weights.
After that,
The Missing Product Layers in AI Safety
Epistemic Status: We’re highly confident in how the larger tech industry defines roles, makes decisions and builds products based on our years of experience in it. We’re fairly confident in the frontier labs operational models based on their job postings. Our suggestions for what to build and how to have gone through some pressure testing, and confidence could be raised through discussion with leaders in AI Safety to further understand what makes this space unique.
Intro
Frontier labs have adopted proven methodologies from tech to build their capabilities using matrixed organizations, including builders. This allows them to advance at a rapid pace, keeping their flywheel spinning, while AI safety struggles to keep up.
To prevent serious risks of advanced AI, AI safety needs to close that gap and one way to accomplish that is by building products that address common needs and diffuse AI safety outputs to compound their impact. There are aligned people that have extensive experience building products, but are not currently finding opportunities in existing organizations or through founder support to build them.
We (the authors and collaborators) each have 10+ years of experience at successful tech startups and in big tech. At EAGxBerkeley, we compared notes on gaps we were observing, our hypotheses on addressing them and wanted to share our perspectives with the broader community.
We’re writing this post to generate awareness, discussion, and ideally to open up discussion with safety leaders, fieldbuilders and funders on how to start building.
Background
An AI safety output spans research, controls, defenses, governance, policy and more. The pace of outputs being generated continues to increase, but there is limited work to connect them back up the chain to the highest level impact of avoiding serious risks to humans. These outputs accumulate in a patchwork of papers, forum posts, blogs, GitHub repositories and more where they rely on a highly-engaged community to continuously discover, consume and adopt. It assumes that the best ideas will win out and gain traction, but provides no formal pathway to achieve that.
We observe a field primarily organized as many small research teams producing many small, loosely coupled artifacts, but lacking layers above those efforts to bring the outputs back together so that they can be quickly applied and adopted by the broader community. For example in the evals tooling landscape Inspect and Petri exist as frameworks but no layer sits above them to standardize the techniques, processes, data and connect all phases of evaluations to ensure that trustworthy results and reporting are generated.
Coefficient Giving’s Fall 2026 Project Tailwind highlights this in multiple areas, such as this challenge statement for their proposed AI uplift for AI Safety initiative:
“There is a coordination failure here: investing in tools and best practices for using AI to accelerate AI safety and governance is a public good that individual contributors often lack capacity for. The individuals already doing this work have limited resources and can’t serve the entire field.”
Threat model
We believe that AI is not normal technology and poses serious risks to humans during both development and deployment across misalignment, misuse, loss of control, and systemic and structural harm. Across all these vectors products and tools play a role in harm reduction (in addition to research and governance). There is awareness of the importance of products [goodgravy 2022, Hobbhahn 2026] and tools [Jones 2021, BlueDot 2025], yet broadly AI safety doesn’t clearly differentiate between the two currently, nor does it robustly support creating products.
Examples of gaps observed in AI safety products and tools
Below is a limited sample of the types of needs we’ve observed across AI safety with concrete references.
Risk vector and Jobs to Be Done | Exists | Missing |
|---|---|---|
Misalignment: know when a model has the wrong objective and why | Products: Neuronpedia Tools: Petri, Bloom, TransformerLens | Access to frontier models beyond black-box [Casper 2024] |
Misuse: |
Additional Course Context (for AI Safety Fundamentals; unofficial)
Context: I created this to share before the start of courses I facilitate to provide a bunch of additional context and frames. I emphasise to students that these posts are to be considered as bonus content—not core curriculum content—and that as such they are really just there for students who want to go deeper, before or after the course. I also provide a lot of links; this is to make it easy for students to follow up anything that catches their interest.
Some general thoughts on advice
I suspect that most advice (including most of the advice I’ve given in the past) is bad. People have very different goals, personalities, skills and opportunities and unless you know someone them really well, it’s hard to cater advice to their circumstances. What one person needs to hear, may be the absolute worst thing for another.
In traditional societies with a slow rate of change, elders are revered. What you’re going through, they’ve lived through and so learning from their experience can save you vast amounts of pain. However, modern Western societies are marked by a much more rapid rate of change and so the experience of elder’s isn’t valued to the same degree. For better or worse, people tend to be much more skeptical that what worked then will still work now. I view the rapid pace of AI progress as greatly exacerbating these kinds of epistemic challenges. I think it’s quite sensible to question how much anyone actually knows about the world we’re going into (I’m referring to both the world in general and AI safety/governance which are constantly shifting fields). Uncertainty is scary, but I see it as a fact of life, one we ultimately need to accept (counterpoint: how often does this end up becoming a form of defeatism?).
Scott Alexander takes this skepticism of advice even further. Rather than just questioning how much we can trust advice, he provocatively suggests that you may want to reverse any advise you hear. People tend choose which groups to join based on whether they resonate with that group’s worldview. Scott suggests that it is often the people who wouldn’t join that group that most need to hear that group’s perspective and that the people who do join such groups who need to listen to the outside world. Unfortunately, groups are very good at taking individuals, solidifying their natural tendencies solidified into an ideology and then amplifying them to an extreme. During this course, you’ll be exposed to many reasons why you should worry more about AI. And perhaps most people should worry more about AI, but perhaps you, personally, are one of the people who should worry less.
(See also Zizek’s criticism of wisdom: “Whatever you do, a wise man will come and justify it”)
Some thoughts on frameworks
People often teach strategy by teaching you frameworks. We’ll be covering a few.
I would argue that every framework has strengths and weaknesses; and that every framework is dependent on certain underlying assumptions.
Not knowing the assumptions or limitations of a framework doesn’t mean they don’t exist; it just means that you don’t know them.
The last few sentences describe a meta-framework. This meta-framework has weaknesses and assumptions as well. Were you nodding along to the previous few lines? If so, do you know the weaknesses and assumptions of the meta-framework I just described. If you didn’t know these, did you know that you didn’t know, or are these an unknown unknown?
Even if a framework is “correct” in some objective sense—humans being humans—it’s still possible that using the framework will on average make your decisions worse. For example, take consistency. Being inconsistent is generally agreed to be objectively wrong, but it’s quite easy to imagine scenarios where someone talks themselves into making a mind-blowingly stupid decision because “I had to be consistent” (with past decisions they couldn’t psychologically admit were mistaken). Frustratingly, it’s also very common for someone to use a framework that is more or less fake to make decisions that are better on net than the decisions they would have otherwise made.
This is quite unfair, but the universe doesn’t have to play nice.
Unfortunately, strategy is hard. Steven Schubert writes: “I think it may be a bit underrated how valuable analysis from the very best analysts of the future of AI is, relative to that of pretty good analysts. It’s such a complex issue it’s easy to miss vital considerations. It pushes the limit of human intellectual ability.”
Cruxes when attempting to predict the future:
- Default beliefs and burden of proof: Do we take claims about transformative AI as highly unusual claims that must satisfy a strong burden of proof, or do we treat these as relatively normal claims on the basis that we already have invented several technologies that would have been almost beyond belief for our ancestors? Is the burden of proof on those who would regulate a technology (ie. a default presumption that regulation is harmful) or on those who want to build it (ie. the company needs to prove their product is safe)?
- Evidence provided by conceptual arguments: Do we treat these as essentially trustworthy if written with a sufficient degree of care and evaluated by folks with good judgement or do we treat them as groundless speculation, at least relative to the null hypothesis or arguments that rely more heavily on empirical results?
- Can we project exponential trends into the future on the basis of induction (ie. the future being like the past) or is this foolish given that exponentials must end at some point? Development of many technologies has occurred as a series of
Meet TokenEconomizer: Microsoft’s Plugin That Cuts Coding Agent Costs by Up to 30.9%
A team of researchers from Microsoft Research and UC Berkeley have released TokenEconomizer, an open-source cost controller for coding agents. TokenEconomizer is a plugin that learns from past sessions in a repository to cut waste in later ones. It works with Claude Code, Codex, GitHub Copilot CLI and Pi. It does not touch model weights or agent code. On 277 SWE-Bench tasks, it lowered mean cost by 18.4% to 30.9% across 5 agent-model settings.
TL;DR
- Package: A standard-library Python package and agent plugins, with 3 switchable mechanisms.
- Runs on: Any machine running Claude Code, Codex, Copilot CLI or Pi with Python 3.10+. No GPU and no API key of its own.
- Performance: 18.4% to 30.9% lower mean SWE-Bench cost, and cheaper in all 30 repository-setting cells.
- Best: 30.9% lower cost on Claude Code with Opus 4.8 (33.2% when combined with RTK).
- Worst: Only 6.4% to 9.3% savings on ReposVul audits; Pass@1 drops 1.0 point on Opus 4.8.
Why do coding agents waste tokens?
Every agent turn re-bills the system prompt, every loaded tool schema and the full history. The research team profiled 60 SWE-Bench tasks across 6 repositories using Claude Code with Opus 4.8. They found 3 recurring sources of waste:
- Repeated discovery: once 5 tasks precede the current one, 30% of tool calls repeat an earlier action.
- Unused tools: 23 tool schemas load every turn. 16 are never called, and 3 cover 98% of calls.
- Failure loops: 10 failed runs were 17% of tasks but 32% of total spend.
They also tested 3 fixed open-source strategies: RTK, Serena and Aider’s RepoMap. None was cheaper everywhere. All 3 cut cost on Django and raised it on SymPy.
How does TokenEconomizer work?
TokenEconomizer is an external controller that treats the agent as a black box. It keeps a state per repository, built from completed traces. Before each task, it sets 3 policies through the prompt, the tool settings and the event stream.
1. Micro-skills
An LLM proposer turns trace digests into 1-line facts, such as the working test command. Each fact carries regex detectors that check later traces without a model call. A fact enters the prompt after 3 confirmations on tasks with non-overlapping edited files. Its need rate must also stay at or above 0.4. One contradiction counts as 5 confirmations, so wrong facts retire quickly.
2. Tool pruning
Shell, read, write and edit tools are always kept. Other tools are masked after 3 consecutive unused tasks, or when an LLM judge marks them irrelevant. The full catalog returns every 5 tasks for a re-audit. On Django with Claude Code, the first request on task 2 fell from 43,351 to 16,295 prompt tokens.
3. Failure-loop intervention
The controller learns a turn budget: 1.25 times the 90th percentile of successful run lengths. Cheap rule checks flag repeated failures or dense errors. An LLM judge then decides if the agent is stuck, at 0.7 confidence or higher. A stuck agent gets 1 redirect, then a stop if the loop recurs.
What do the SWE-Bench results show?
| Setting | Cost vs default | Pass@1 default | Pass@1 TokenEconomizer |
|---|---|---|---|
| Claude Code + Sonnet 5 | -23.6% | 74.7 | 76.0 |
| Claude Code + Opus 4.8 | -30.9% | 74.0 | 73.0 |
| Codex + GPT-5.6 Terra | -24.7% | 73.8 | 74.7 |
| Codex + GPT-5.6 Sol | -26.1% | 80.1 | 81.7 |
| Copilot CLI + Sonnet 5 | -18.4% | 75.0 | 77.6 |
Source: arXiv 2610.22732, Table 1. Costs include all controller calls. 3 seeds per setting.
Pass@1 improved in 4 of 5 settings. Lower reasoning effort saved cost but cut Pass@1 by 1.8 to 10.3 points. RTK alone raised cost in 12 of 30 repository-setting cells, and RepoMap in 15.
Savings build over time. Most repositories cost more at first, but all were cheaper by the sixth task. Alone on Claude Code, tool pruning saved 13.2% to 17.7%, micro-skills 11.8% to 14.3%, and the loop guard 5.4% to 7.1%.
Results also held outside SWE-Bench. Costs fell 16.0% to 21.2% on Web-Bench and 16.5% to 19.6% on CredData. ReposVul saw only 6.4% to 9.3%, because shorter runs leave less to remove.
How does it compare with other token-saving tools?
| Feature | TokenEconomizer | RTK | Serena | Aider RepoMap |
|---|---|---|---|---|
| Approach | Learns per-repository policies from past sessions | Compresses shell command output | MCP server with symbol-level code tools | Ranked map of repository symbols in the prompt |
| Learns from earlier tasks | Yes | No | No | No |
| License | Apache 2.0 | Apache 2.0 CLI; BUSL-1.1 engine | GPL-3.0-or-later (MIT for SolidLSP) | Apache 2.0 |
| Agents | Claude Code, Codex, Copilot CLI, Pi | 18 AI coding tools | Any MCP client | Aider |
| Mean SWE-Bench cost change (paper, 5 settings) | -18.4% to -30.9% | -8.9% to +4.5% | Not in main runs (raised pooled cost in profiling) | -6.1% to +6.5% |
| Cells with higher cost (of 30) | 0 | 12 | Not disclosed | 15 |
Cost rows: TokenEconomizer paper. Licenses and claims: each project’s repository or docs.
How do you install TokenEconomizer?
The plugin needs one of the 4 agents and Python 3.10 or newer. On Claude Code, clone the repo, add it as a marketplace, then run claude plugin install tokeneconomizer@tokeneconomizer. Learned data stays local in ~/.tokeneconomizer. Tool p