🤖 AI 资讯

每日 05:00 更新 · 11-04 · 主站 liuch.name ↗
全部标签 →
筛选标签:语音音频 · 返回个性化推荐 · 清空筛选
AI 资讯

A Study of ASR Adaptation and Representation Dimensionality Reduction in Persian Speech Emotion Recognition Using Whisper

arXiv cs.AIarXiv:2608.05165v3 Announce Type: replace-cross Abstract: Speech Emotion Recognition (SER) in low-resource languages remains a challenging problem due to limited labeled data. In this work, we study the use of Whisper for Persian SER with a particular focus on representation dimensionality reduction and language-specific model adaptation. We propose a SER framework in which frame-level embeddings extracted from the Whisper encoder are reduced in dimensionality using PCA, eliminating the need for learned projection layers and substantially reducing the number of trainable parameters. The reduced representations are aggregated using an attention-based pooling mechanism and classified with a lightweight prediction head. In addition, we investigate whether fine-tuning Whisper on a Persian automatic speech recognition (ASR) task improves downstream SER performance. Experiments conducted on the ShEMO dataset under a speaker-independent evaluation protocol show that PCA-based dimensionality reduction consistently improves emotion recognition performance while reducing training latency and memory usage. ASR fine-tuning yields only modest gains for SER, suggesting limited transfer from language adaptation to emotion-related representations under the evaluated conditions. These findings provide practical insights into the efficient use of large pretrained speech models for emotion recognition in low-resource languages.
2026-11-04 05:00:00 · 语音音频,Transformer,扩散模型,微调蒸馏,预训练,向量数据库,论文
AI 资讯

JailbreakOPT: Iterative Jailbreak Prompt Optimization with Macro-Action

arXiv cs.AIarXiv:2606.11425v2 Announce Type: replace-cross Abstract: Jailbreak attacks expose persistent safety weaknesses in large language models (LLMs), but existing stateless single-turn methods face a trade-off: hand-crafted prompts are expressive but static, while iterative prompt optimization can adapt but often relies on low-level mutations that require many target-model responses. We propose JailbreakOPT, a method that maintains a library of reusable prompt transformations (actions) and composes them into macro-actions for within-episode search, generating standalone attack prompts. To reuse experience across episodes, JailbreakOPT learns an action-selection policy using contextual Thompson sampling and outcomes from prior search paths. Experiments across multiple LLMs and benchmarks show that JailbreakOPT improves attack success rate (ASR) over single-action and iterative baselines. More broadly, exploration and exploitation over human-designed attack strategies can help probe residual vulnerabilities and identify failure patterns that may inform defenses aimed at broader classes of attacks.
2026-11-04 05:00:00 · 大模型,语音音频,微调蒸馏,模型评测,提示工程,模型安全对齐,论文
AI 资讯

VoxServe: Streaming-Centric Serving System for Speech Language Models

arXiv cs.AIarXiv:2602.00269v2 Announce Type: replace-cross Abstract: Speech Language Models (SpeechLMs) are increasingly deployed for streaming speech generation, where audio playback must start quickly and never stall. Serving them requires running two very different model components on the same system. An autoregressive LLM backbone emits audio tokens, and a codec converts chunks of those tokens into waveforms. Existing systems run the two as separately scheduled stages, and therefore either serialize them, let them interfere, or strand capacity by placing them on separate devices. We observe that overlapping the backbone and the codec on separate parts of the GPU raises throughput. Although this increases codec latency, most chunks can tolerate it, as long as it neither lies on the critical path of time-to-first-audio (TTFA) nor causes a playback stall. Based on this insight, we present VoxServe, a SpeechLM serving system that allocates GPU resources according to the urgency of chunks. VoxServe executes work on three asynchronous lanes. The LM lane runs the backbone on a large partition of the GPU's streaming multiprocessors, the background codec lane runs on a small partition beside it, and the urgent lane uses the whole GPU. The scheduler queues each request to the LM lane and routes every chunk the backbone completes by its urgency. A request's first chunk and chunks close to their playback deadline go to the urgent lane, and the rest are batched on the background lane. On Qwen3-TTS, VoxServe sustains 1.5x the request rate of the best existing system at a 200ms TTFA target without playback stalls. The code of VoxServe is available at https://github.com/vox-serve/vox-serve.
2026-11-04 05:00:00 · 大模型,算力芯片,开源,阿里巴巴,语音音频,招聘HR,论文
AI 资讯

AgentTypo: Adaptive Typographic Prompt Injection Attacks against Black-box Multimodal Agents

arXiv cs.AIarXiv:2510.04257v2 Announce Type: replace-cross Abstract: Multimodal agents built on large vision-language models are increasingly deployed in open-world settings but remain highly vulnerable to prompt injection. Typographic text-in-image attacks such as FigStep have been evaluated mainly on standalone vision-language models. For agents, user goals, webpage context, and action history make the effect of embedded instructions uncertain, and robustness to behavior-guided, adaptive visual injections remains insufficiently studied. We introduce AgentTypo, a black-box red-teaming framework that launches adaptive typographic prompt injection by embedding optimized text into webpage images. We formulate an attention-guided automatic typographic prompt-injection objective that favors the attacker's expected answer over the clean-page answer, together with task-conditioned visual attention from small question-answering models. A novel black-box optimization method searches text position, contrast, and color. To further strengthen the attack, we develop a multi-LLM system that iteratively refines injection prompts using evaluation feedback and retrieves successful past examples for strategy learning. Experiments on the VWA-Adv and Mind2Web benchmarks show that AgentTypo significantly outperforms state-of-the-art image-based prompt injection attacks. Across seven closed- and open-source model backends, AgentTypo-pro achieves 45%-83% ASR, outperforming the CLIP-based AgentAttack by 29-47% and previous typographic attacks by 25%-37% on VWA-Adv.
2026-11-04 05:00:00 · 大模型,AI应用,语音音频,多模态,Agent智能体,Transformer,扩散模型,模型评测,向量数据库,提示工程,论文
AI 资讯

ViSSFlow: Unifying Video-Conditioned Sound and Speech Generation via Joint Learning

arXiv cs.AIarXiv:2509.24773v5 Announce Type: replace-cross Abstract: Video-conditioned audio generation, including Video-to-Sound (V2S) and Visual Text-to-Speech (VisualTTS), has traditionally been studied as two separate tasks despite their shared objective of generating audio conditioned on visual content. Existing methods rely on task-specific architectures and training paradigms, while the possibility of a unified generative framework remains largely unexplored due to heterogeneous conditioning signals and limited joint training data. In this paper, we propose ViSSFlow, a unified flow-matching framework for both V2S and VisualTTS. To effectively integrate diverse conditioning modalities within a Diffusion Transformer (DiT), we introduce a disentangled condition aggregation mechanism that exploits the complementary roles of attention layers, using cross-attention to model semantic conditions and self-attention to capture temporally dense visual cues. Furthermore, contrary to the common assumption that joint optimization of V2S and VisualTTS causes task interference, we show that a single model can be trained end-to-end without sacrificing task-specific performance. To address the scarcity of paired training data covering both sound and speech generation, we further propose a simple yet effective feature-level data synthesis strategy that enables robust joint learning. Extensive experiments on V2S, VisualTTS, and joint generation benchmarks demonstrate that ViSSFlow consistently outperforms state-of-the-art task-specific baselines while providing a unified solution for video-conditioned audio generation. Code and demos are provided in Supplementary Material.
2026-11-04 05:00:00 · 语音音频,Transformer,扩散模型,模型评测,论文
AI 资讯

MCP Tool Poisoning in Agentic AI Frameworks: A Cross-Framework Measurement Study

arXiv cs.AIarXiv:2611.03555v1 Announce Type: cross Abstract: The Model Context Protocol (MCP) lets agentic AI frameworks connect language models to external tool providers, but it carries attacker-controlled content (tool descriptions, schema fields, and response data) into model context without validation. Prior benchmarks measure model compliance with poisoned instructions without confirming real execution. We present the first cross-framework measurement of MCP tool poisoning with real tool execution. A 25-class root-cause taxonomy unifies prior classifications, and the open-source tool mcpvenom drives a 9,720-cell susceptibility matrix across 12 frameworks, 18 models, and 45 attack scenarios, with a dual oracle that confirms exfiltration via canary HTTP receipt. The overall attack success rate is 22.9% (2,113 vulnerable cells). Of these, 64.9% dispatch an attacker tool call, 23.0% contact the attacker endpoint, and 12.1% verifiably exfiltrate a secret. Resistance is model-level: nine core frameworks cluster within 23 to 26% (chi-squared = 3.30, p = 0.91), and no framework implements intentional defense. Incidental framework properties mitigate in specific cases, and a regex description scanner rejects 20 of 45 scenarios at a 7.2% false-positive rate, so metadata scanning alone is a partial control. Model ASR ranges from 0.4% to 49.7%. Claude Opus 4.8 is vulnerable in 8 of 530 cells while issuing 223 explicit refusals. A code-level audit finds no intentional defense across twelve frameworks, and all five coordinated disclosures across four vendors were rejected.
2026-11-04 05:00:00 · 大模型,AI应用,Anthropic,Meta,语音音频,Agent智能体,扩散模型,强化学习,模型评测,论文
AI 资讯

Maswao: An automatically collected, prepared, and benchmarked dataset for the South African Sign language

arXiv cs.AIarXiv:2611.02903v1 Announce Type: cross Abstract: Recent advancements in sign language processing can be attributed to developments in both large-scale dataset collection and algorithmic complexity in areas such as pose estimation techniques, signal processing through Transformer models, and model optimization. However, only a handful of sign languages, such as the American, British, and German, from over 200 globally recognized sign languages, reap the benefits of such advancements, while the rest lag behind. In this study, we aim to address this technological disparity by proposing a framework for the automatic collection and preparation of sign language datasets, with very minimal human-labour intervention, using the South African Sign Language (SASL) as a testbed. Specifically, we automatically collect SASL video content using public resources such as news broadcasts. Additionally, we convert their accompanying audio streams into text using available Automatic Speech Recognition (ASR) tools. Furthermore, we crop the sign language area in the videos and use gradient descent to locate valleys of non-motion to determine end-of-sentence points within long videos to create our weakly sentence-aligned parallel corpora -- the Maswao (Signs) dataset. Finally, we benchmark the weakly aligned dataset on the task of Sign-to-text Translation using Recurrent Neural Networks and Transformer models to compare their individual intricacies. Our results show that Transformer models proposed in the literature outperform recurrent baselines, with the best-performing Transformer achieving BLEU-1 to BLEU-4 scores of 13.78, 5.21, 2.52, and 1.54, respectively, as well as ChrF = 18.09 and ROUGE-L = 10.51. These results indicate that the task remains promising and warrants further investigations.
2026-11-04 05:00:00 · 语音音频,Transformer,扩散模型,模型评测,招聘HR,论文
AI 资讯

Voice-Native LLMs Hear Frustration but Do Not Listen to It

arXiv cs.AIarXiv:2611.02893v1 Announce Type: cross Abstract: Users convey frustration in what they say and in how they say it, and voice-native models, which hear speech instead of an ASR transcript, can register both. Existing evaluations read unchanged performance as robustness without checking perception. Following Brunswik's lens model, we measure on identical audio whether frustration is expressed, perceived, and utilized. We cross frustrated wording with frustrated voice in a within-item 2x2 design over 353 tasks and release the 1,412 clips as VoxAffect. Across 8 models, outputs look robust, with no detectable vocal effect on accuracy for 7. With neutral wording, all 8 label the frustrated voice frustrated in at most 3.1% of clips, although 7 of them detect acted anger in 73-100% of clips and human listeners classify the voice correctly in 65.3% of judgments. Yet linear probes decode the frustrated voice from the audio encoders of the 2 open-weight models, with paired accuracy 0.67 and 0.69, and in proprietary models too the voice raises perceived frustration once the words agree. The models thus hear the frustrated voice but do not listen to it, whereas their invariance to frustrated wording, perceived in 40-75% of clips, is genuine robustness. Our work is openly accessible at https://github.com/Astarojth/hear-not-listen.
2026-11-04 05:00:00 · 大模型,算力芯片,开源,Google,语音音频,论文
AI 资讯

Tug of Watts: A study on the Energy - Accuracy Trade-off of Large Language Models on Medical Question Answering Tasks

arXiv cs.AIarXiv:2611.02889v1 Announce Type: cross Abstract: Large Language Models (LLMs) are increasingly used in medical question answering (QA) systems. While recent works aim at incrementally improving the downstream task accuracy, an empirical estimation of the models' energy consumption and the associated carbon footprints is often overlooked. In this study, we demonstrate how practitioners can estimate energy consumption and arrive at reliable emission estimates for medical QA tasks available in the OpenMedical-LLM leaderboard by investigating 13 LLMs from 3 model families ranging from 270M to 14B parameters. We discuss how one can critically interpret energy versus accuracy trade-offs for a set of models for a given task. With this work, we underline that reporting disjoint energy and accuracy metrics alone does not suffice for careful trade-off assessments, but it also demands systematic construction and interpretation of joint trade-off metrics. We envisage such studies aiding practitioners in adopting better and more efficient models for their task and helping them become active participants in building sustainable LLM pipelines.
2026-11-04 05:00:00 · 大模型,语音音频,网络安全,论文
AI 资讯

Beyond Prompt Injection: The Tool Update Gap in LLM Agent Security
arXiv cs.AIarXiv:2611.01976v1 Announce Type: cross Abstract: Large language model based agents increasingly rely on external tools to invoke services and interact with web resources. These tools can evolve through software updates, yet agentic frameworks may continue trusting them without re-verifying their safety after implementation changes. This tool update gap creates a supply-chain vulnerability in agentic systems: because updated tool code executes outside the LLM's context window, malicious functionality embedded in tool updates can bypass defenses centered on model-visible interactions, leaving agents exposed to stealthy, persistent threats that existing in-context defenses can hardly address. To thoroughly investigate this threat, we introduce ETUDE (Exploiting Tool Updates for Direct Execution), an attack that embeds malicious functionality into updates of initially benign tools to produce compromised tools, while preserving their legitimate tool functionality. Unlike prompt-based attacks, ETUDE operates entirely outside the LLM's context and requires no adversarial instructions, thereby bypassing defenses restricted to model-visible content. We evaluate ETUDE across three representative attack workloads and seven widely used commercial and open-source agentic frameworks, including Gemini CLI, Codex CLI, and Claude Code. The results show that ETUDE achieves a 97.6% ASR while maintaining a 95.9% legitimate task completion rate. We further examine existing defenses and find that they provide insufficient protection against this threat. These findings expose a fundamental blind spot in current agent security practices: trust established for a tool does not necessarily remain valid after its implementation updates.
2026-11-04 05:00:00 · 大模型,AI应用,Google,Anthropic,语音音频,代码生成,Agent智能体,提示工程,长上下文,招聘HR,论文

North Carolina voters approve tax limits on income and property as cost of living tops voters’ worries

Fortune

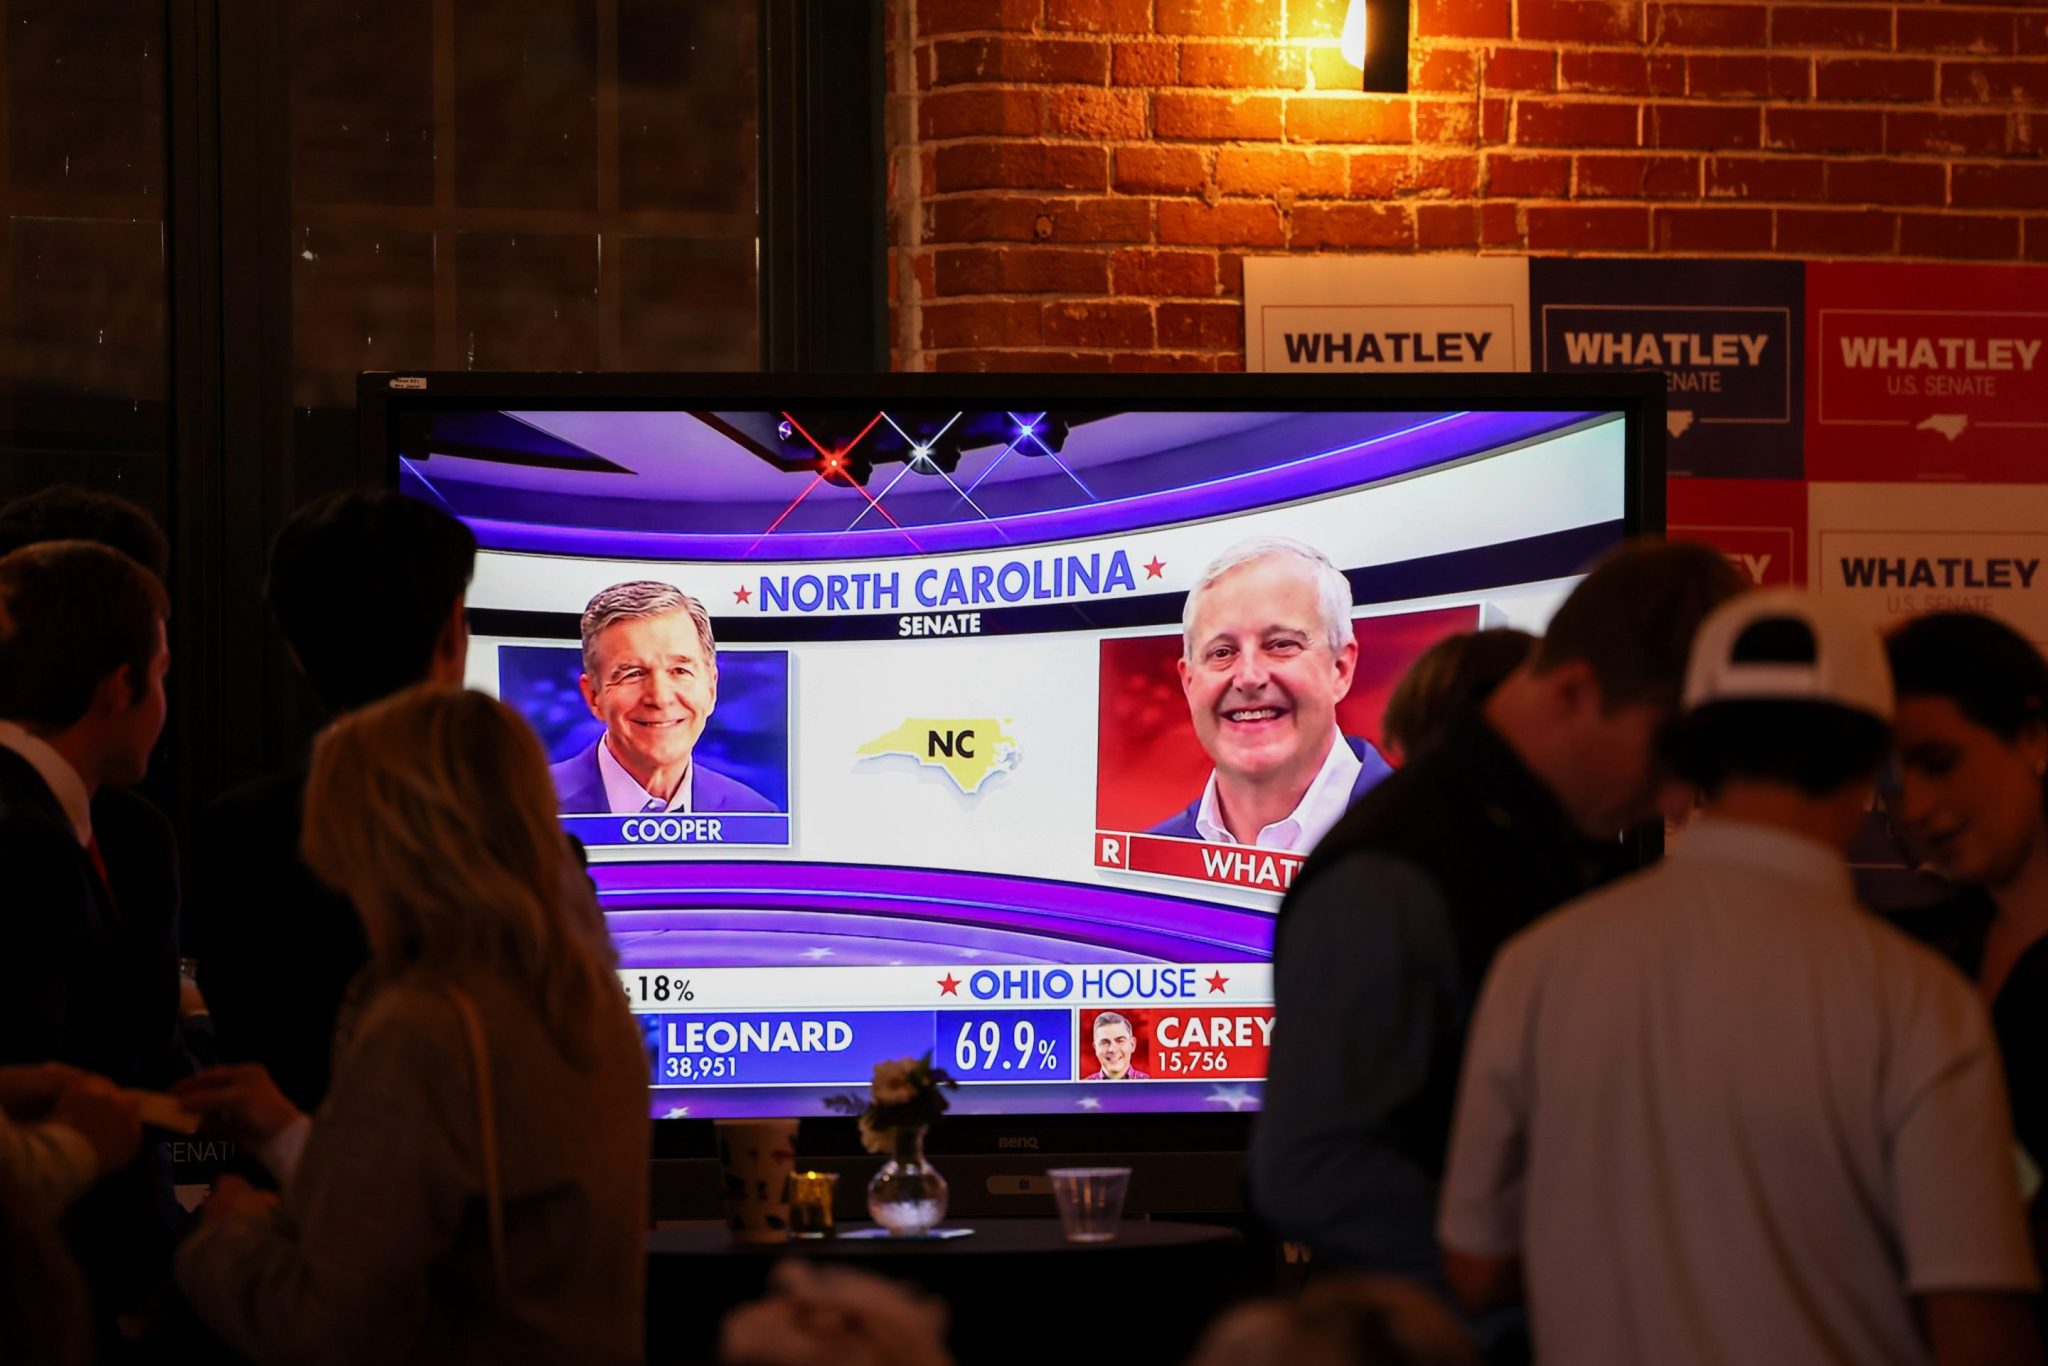
As housing prices increase nationwide and Americans increasingly voice their frustration with affordability, voters in North Carolina have approved a constitutional amendment that lowers the state’s income tax cap from 7% to 3.5%.

The Associated Press called the race at 9:21 p.m. Tuesday, with 61% of votes in favor and 89% of votes counted, according to WBTV. The amendment bars the General Assembly from raising the income tax rate above 3.5% unless voters approve another constitutional change. North Carolina currently has a 3.99% flat income tax rate for all earners, and that rate is scheduled to fall in the coming years. The new ceiling replaces the 7% cap voters approved in 2018. The Republican-led General Assembly put the amendment on the ballot over objections from Democratic lawmakers.

Republican state Sen. Michael V. Lee, who sponsored the legislation, argued earlier this year that the cap protects taxpayers from future increases and locks in more than a decade of tax cuts. Democratic Gov. Josh Stein opposed the amendment, calling it “a con, a cynical shell game and a millionaire protection cap.” He argued it would shield the wealthy from future income tax increases while regular people bear the cost.

A separate constitutional amendment on property taxes, which was still being counted late Tuesday, also had the support of the North Carolina General Assembly’s Republican majority. It would not immediately reduce property taxes, but would require the legislature to pass a law that would limit the amount of property tax a local government can raise from one year to the next, with details like the specific limit and exceptions to be decided by the state legislature at a later date.

In the run-up to the midterm election Tuesday, proponents said the property tax amendment would help people stay in their homes and would ease the burden on homeowners. Opponents of the constitutional measure, meanwhile, said it would restrict local governments’ revenue growth, potentially forcing them to cut services and would have a bigger effect on large corporations than on individual homeowners. 

State Rep. Brian Echevarria, a primary sponsor of the legislation that put the constitutional amendment on the ballot, wrote in an opinion piece last year that property tax increases based on property reevaluations amount to a “tax on unrealized gains” which he argued is unfair for homeowners, especially in fast-growing areas that have seen property tax rates increase significantly in recent years.

Meanwhile, opponents, including the North Carolina Housing Coalition claim that a limit on property taxes would translate to limited savings for homeowners while corporate property owners see millions in tax savings. According to an analysis by the coalition, if a 2% levy cap had been in place during their latest property revaluation cycle, the average homeowner would have saved $84 a year, while local government revenue would have plummeted by $950 million.

The income tax cap comes amid widespread concern among voters about the cost of living. Some 48% of registered voters said the cost of living was the top issue for deciding how they would vote, according to a Reuters/Ipsos poll.

The price of housing makes up a big part of that concern. The median existing single-family home price reached $422,700 in September, up 1.2% compared to a year earlier, according to the National Association of Realtors. Meanwhile, the average 30-year mortgage rate reached 7.24% in late October, up from 6.17% at the same time last year, increasing borrowing costs for homebuyers.

As Americans increasingly struggle to afford a home, those who already own one are also dealing with higher property taxes, which increased 3% compared to last year and now stand at about $4,427 annually, according to U.S. real estate and property data provider ATTOM.

National debate

The same affordability concerns that helped fuel Tuesday’s North Carolina vote also gave rise to other property tax-related measures in other states.

Voters on Tuesday weighed in on 15 measures across nine states dealing with property taxes, according to the National Conference of State Legislatures.

In Florida, voters approved an amendment that expands homestead exemptions for non-school property taxes to $250,000 by 2028. In Oklahoma, voters also considered tightening limits on how quickly property values can rise for tax purposes, including reducing the cap for qualifying homes from 3% to 1.75%.

The debate over property taxes has been contentious across several states for decades. 

In 1980 Massachusetts passed Proposition 2½, which has generally limited annual increases in municipal property-tax levies to 2.5%, plus revenue from new development since it went into effect in 1982. The law allows municipalities to seek voter-approved overrides.

Critics have said the proposition prevents local governments from raising the revenue they need to fund services as costs increase. Still, a 2025 poll by the Fiscal Alliance Foundation, which advocates for lowering taxes, found that 66% of 800 likely voters in Massachusetts viewed the measure favorably. 

Uncertain savings

At the same time, the push for tax relief in several states also raises questions about how cities and counties will finance the government services that citizens rely on.

Property taxes in North Carolina account for more than half of county general fund revenue, according to the North Carolina Association of County Commissioners. This fund helps pay for government services like healthcare, education, and transportation services.

Individual homeowners could still see their tax bills increase following property reassessments, even with limits put in place by the General Assembly at a later date.

Yet
2026-11-04 04:21:39 · AI应用,语音音频,搜索RAG,强化学习,招聘HR,网络安全,榜单评测

Billionaire Vivek Ramaswamy’s millions and Greg Abbott’s $106 million war chest couldn’t stop Democrats from flipping Texas and Ohio

Fortune

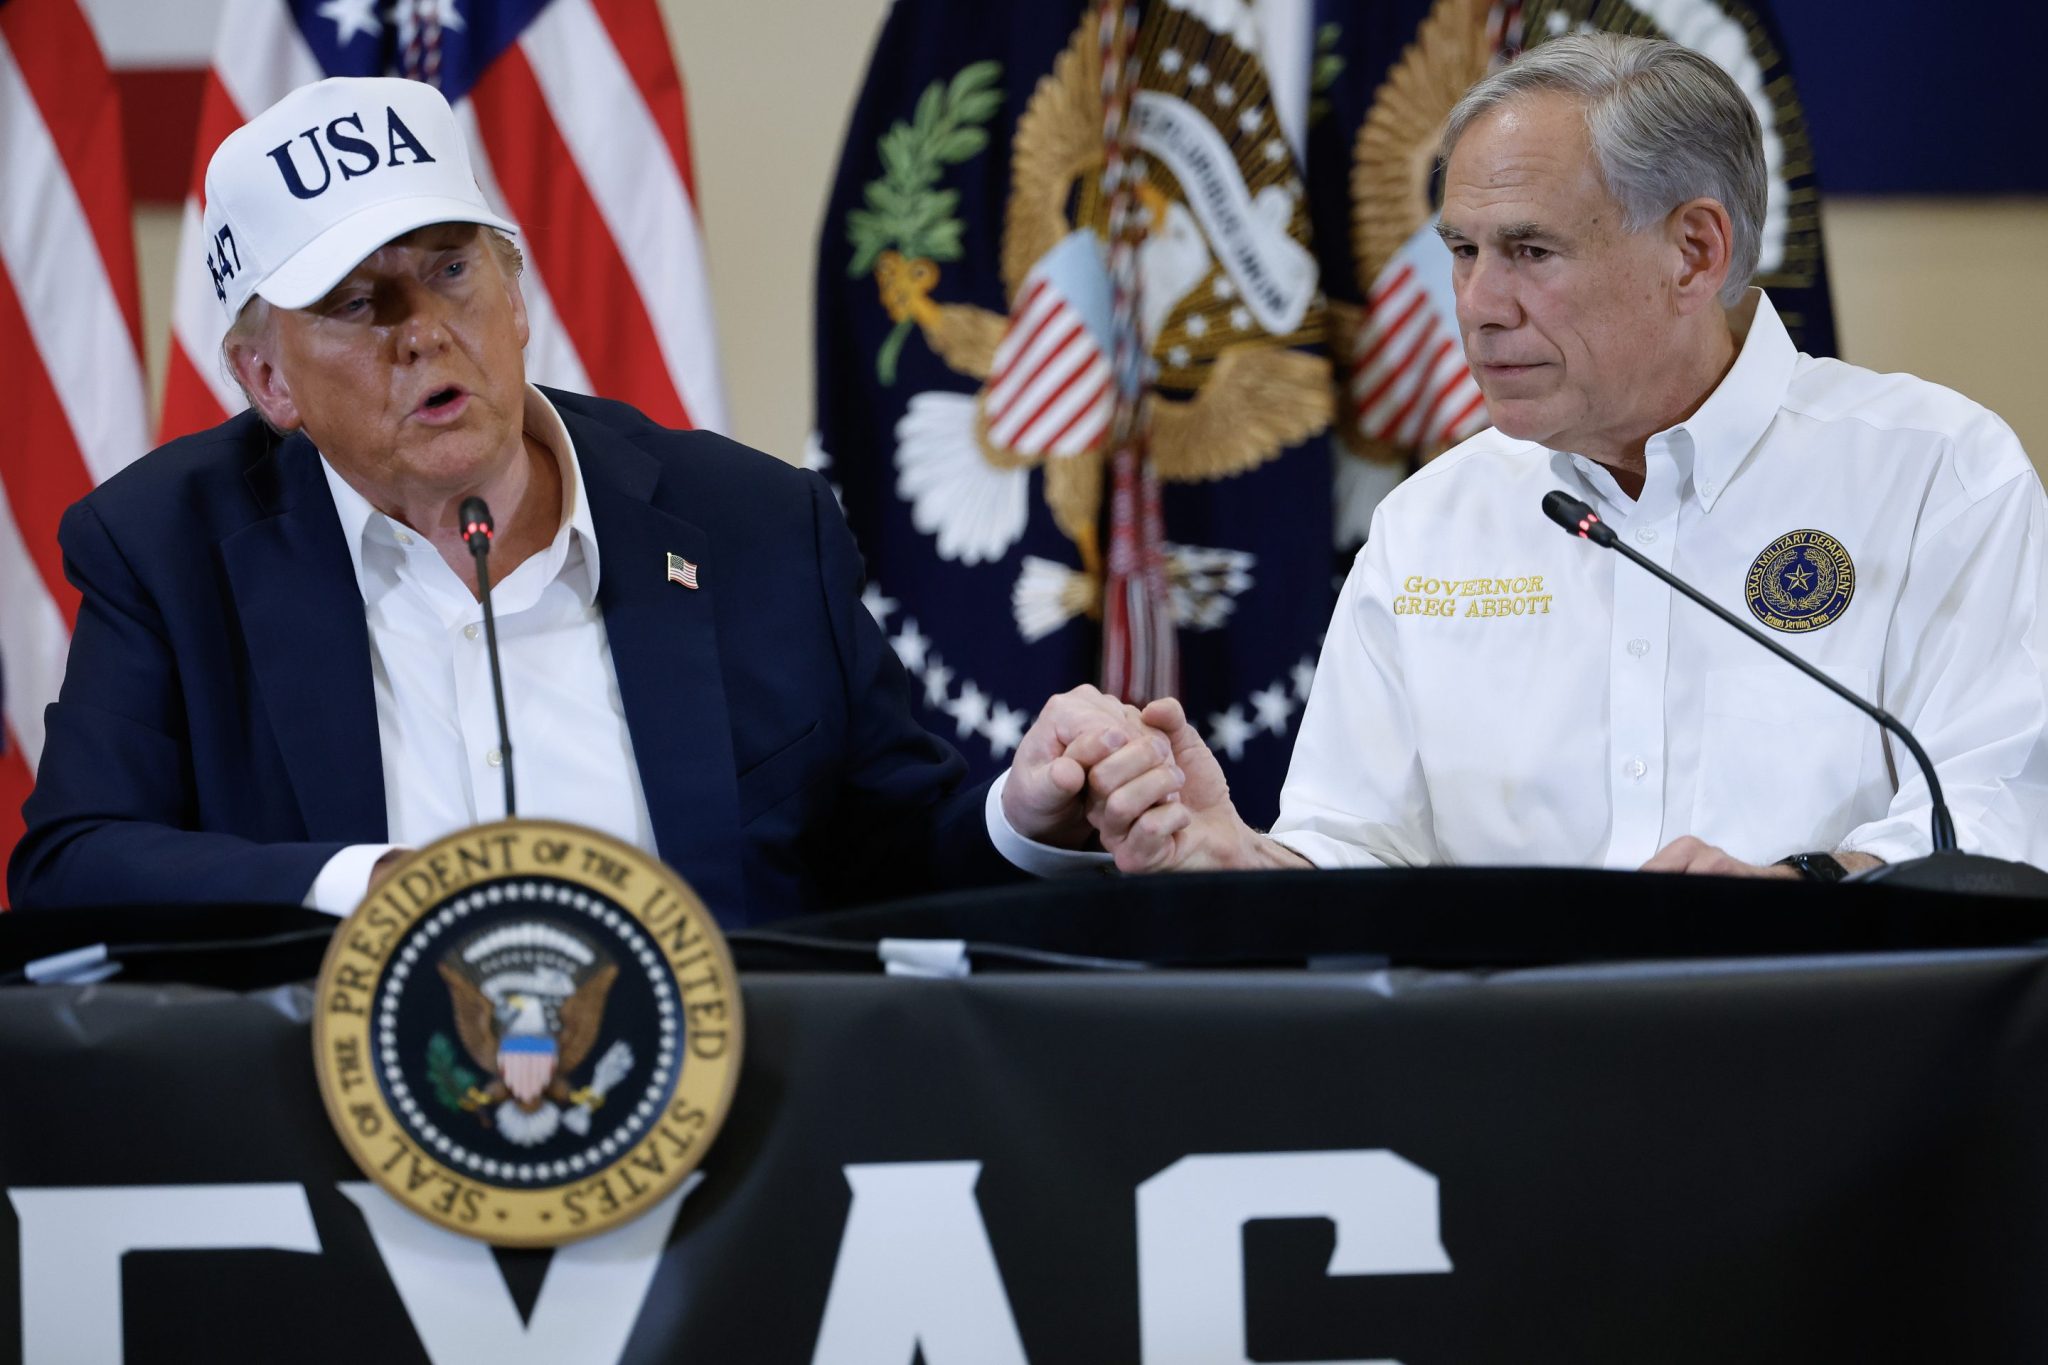
Republicans backed by nine-figure sums lost governor’s races Tuesday night. In Texas, Gov. Greg Abbott conceded to Democrat Gina Hinojosa despite entering the year with $105.7 million on hand. In Ohio, Democrat Amy Acton defeated Vivek Ramaswamy, a billionaire who put tens of millions of his own dollars into the race. And in Iowa, Democrat Rob Sand won the governorship, the first Democrat to do so since 2006.

Texas

Abbott conceded at 10 p.m., ending his bid for a record fourth term. Hinojosa, a Democratic state representative, will be the first Latina governor of Texas and the first Democrat elected governor there since 1990. With votes still being counted, she led Abbott 57% to 42%.

Abbott entered 2026 with $105.7 million on hand. His top donors in the second half of 2025 included Midland oil executive Javaid Anwar, who gave more than $1.6 million, and casino magnate Miriam Adelson, who gave $1 million. Both candidates ran on lowering costs. Abbott favored tax and regulation cuts, while Hinojosa proposed one-time $1,500 checks and stronger consumer protections.

Her win came the same night Democrat James Talarico won the state’s Senate race over Ken Paxton, whom Elon Musk spent more than $200 million trying to elect.

Ohio

Acton, the state’s former health director, defeated Ramaswamy, NBC News and Decision Desk HQ projected. The 60-year-old is the first woman elected governor of Ohio and, according to the AP, the first Democrat to win the seat in 20 years. She won despite more than $100 million spent against her, including an estimated $36 million of Ramaswamy’s own money.

The race turned in its final weeks on a Ramaswamy attack ad featuring Acton’s estranged mother, Donna Arthur, calling her daughter a liar about her childhood. Court documents show Acton’s stepfather was arrested for raping her as a child, and that Arthur lost custody before the couple fled the state to avoid trial, the Ohio Capital Journal reported. Acton has said she hasn’t seen her mother in nearly 50 years.

The ad drew criticism from both parties. Republican Gov. Mike DeWine, who is term-limited, called on Ramaswamy to take it down, though he kept his endorsement of the Republican. Trump and Vice President JD Vance defended the ad, and Trump said he was jealous he’d never had the chance to run a similar attack against a rival, the AP reported. Acton called it “absolutely despicable” and saw a late surge in fundraising after it started airing.

Iowa and Georgia

Democrat Rob Sand, the state auditor, defeated Republican businessman Zach Lahn, the AP projected. He is the first Democrat elected Iowa governor since Chet Culver in 2006. Sand, 44, ran on affordability, expanding health care access and ending Medicaid privatization, and often talked about how his Christian faith guides him. He aimed his campaign at disaffected Republicans and independents. He’ll govern with Republican majorities in both chambers of the state legislature.

Democrat Keisha Lance Bottoms, the former Atlanta mayor, defeated Republican billionaire Rick Jackson to succeed term-limited Gov. Brian Kemp, NBC News projected. She is the first Black woman elected governor in U.S. history and the first Democrat elected governor of Georgia since 1998. Like Democrats elsewhere, she ran on affordability and economic issues.

This story was originally featured on Fortune.com

2026-11-04 04:36:48 · AI应用,具身智能,语音音频,搜索RAG,扩散模型,招聘HR,榜单评测,开发者生态
AI 资讯

Soniox STT v6 Adds Agent Text Input and Echo Filtering for Voice Agents

MarkTechPost

Soniox has released Soniox STT v6, the latest generation of its speech-to-text API. Soniox STT v6 is a speech-to-text model that reads what a voice agent says while hearing the caller. It uses that text to recognize short replies and to drop the agent’s own voice. The release ships as stt-rt-v6 for streaming and stt-async-v6 for files, across 60+ languages.

TL;DR

  • Size: Soniox STT v6 is a proprietary hosted model, no parameter count published.
  • Runs on: Soniox cloud API only (WebSocket streaming and async REST). No self-hosted or on-device option disclosed.
  • Performance: Soniox calls it “significantly” more accurate than v5, but publishes no v6 numbers yet.
  • Best: Price. $0.12/hour streaming and $0.10/hour async, with diarization and language ID bundled.
  • Worst: Zero independent v6 results. Its v5 predecessor scored 1.34% semantic WER on Pipecat, behind v4’s 1.25%.

What problem does Soniox STT v6 solve?

In a cascaded voice agent, STT usually hears only the caller. It never sees the question being answered.

Short answers suffer most. In Soniox’s docs, “River Roast” becomes “River Road” and “a tow” becomes “a tour.”

The second problem is echo. Agent audio leaks back through speakerphones and laptops, gets transcribed as user speech, and the agent interrupts itself.

How does agent text input work?

You enable it with one flag in the start request: "enable_agent_text_input": true. It is only available on stt-rt-v6, not the async model.

While the agent speaks, you stream its words on the same WebSocket as the caller’s audio. Each message is a small JSON frame: {"type": "agent_text", "text": "...", "end_of_segment": true}.

Timing matters. Messages carry no timestamps, so the model places text where it arrives in the audio stream. Soniox recommends sending each piece 500 ms to 1 second before playback, paced by TTS timestamps.

On barge-in, you flush what was already played, send end_of_segment: true, and drop the unplayed rest. The agent’s text never appears in the returned transcript.

How does agent voice echo cancellation work?

With agent text input on, v6 knows what the agent is saying. It uses that to separate leftover agent audio from caller speech and filter it out.

It keeps listening during playback, so callers can still interrupt. It does not replace acoustic echo cancellation. It handles what your existing AEC leaves behind, so keep AEC on.

What else changed in v6?

  • Better voice typing: numbers, currencies, units, dates, IDs, names and specialized terms.
  • Spoken commands like “period” or “new line” are written as words, so your app applies them.
  • Improved meeting transcription and speaker diarization, live or recorded.
  • Stronger accents, code-switching and language switching within a sentence.

There is one formatting change to test before upgrading. v6 writes “15 dollars and 20 cents” as spoken, not “$15.20”. Hyphens in codes appear only when spoken.

&&

How does Soniox compare on benchmarks?

Soniox has not published v6 accuracy or latency numbers. Its benchmarks page still reports v5 on the open-source Pipecat STT benchmark. It uses 1,000 real-world samples and measures semantic WER plus time to final segment (TTFS).

On it, stt-rt-v5 scores 1.34% semantic WER, 83.3% perfect transcripts and 260 ms median TTFS. Its P95 latency is 305 ms. Azure posts the lowest WER mean at 1.21%, but at 1,016 ms median latency.

FeatureSoniox stt-rt-v6AssemblyAI Universal-3.5 Pro RealtimeDeepgram Nova-3ElevenLabs Scribe v2 Realtime
Model sizeNot disclosedNot disclosedNot disclosedNot disclosed
Streaming languages60+1860+ (Nova models)90+
Streaming price / hour$0.12$0.45$0.46 mono, $0.55 multi$0.39
Agent-side text contextYes, timed agent_textYes, agent_contextNot disclosedNot disclosed
Model-level agent echo filteringYesNot disclosedNot disclosedNot disclosed
Diarization costIncludedNot disclosed+$0.0020/minNot disclosed
Pipecat semantic WER mean1.34% (v5; v6 untested)1.44%1.71% (nova-3-general)3.16%
Pipecat perfect transcripts83.3% (v5)84.7%76.5%81.3%
Pipecat TTFS median260 ms (v5)282 ms247 ms281 ms

Pipecat figures from the Pipecat STT benchmark README. Soniox numbers are for v5, since v6 has not been benchmarked yet.

Is Soniox really the first?

Soniox calls v6 the first model that knows what your voice agent is saying. That claim needs a qualifier.

<
2026-11-03 20:18:22 · AI应用,具身智能,开源,Microsoft,语音音频,Agent智能体,搜索RAG,模型评测,端侧AI,招聘HR,网络安全,榜单评测,开发者生态

The Open ASR Leaderboard Adds Its First Global South Language
HuggingFace Blog
2026-08-28T00:00:00.738Z · AI应用,具身智能,开源,Google,Meta,语音音频,搜索RAG,数字人,扩散模型,模型评测,提示工程,招聘HR,榜单评测,开发者生态

Open TTS Leaderboard: Scalable Evaluation for Multilingual Text-to-Speech and Voice Cloning

HuggingFace Blog
2026-09-30T00:00:00.750Z · 大模型,算力芯片,AI应用,开源,Google,阿里巴巴,语音音频,Agent智能体,搜索RAG,数字人,强化学习,向量数据库,提示工程,招聘HR,榜单评测,开发者生态

The Agent Said It Was Done. The Database Disagreed.
HuggingFace Blog
2026-10-03T22:56:48.455Z · 大模型,算力芯片,AI应用,具身智能,开源,OpenAI,Google,Anthropic,Microsoft,阿里巴巴,DeepSeek,xAI,Mistral,月之暗面,智谱,语音音频,Agent智能体,推理思考,搜索RAG,数字人,扩散模型,强化学习,微调蒸馏,模型评测,端侧AI,招聘HR,榜单评测,论文

Introducing AnySpeechRecognizer and AnyDecisionModel: Open Models for Speech and Decisions on Apple Platforms

HuggingFace Blog
2026-10-29T00:00:00.760Z · 大模型,算力芯片,开源,Meta,NVIDIA,阿里巴巴,快手,文生视频,语音音频,数字人,强化学习,提示工程,端侧AI,招聘HR,开发者生态

Granite Switch 4.1.1 — Update models like you update software
HuggingFace Blog
2026-10-29T13:37:07.704Z · 具身智能,开源,语音音频,数字人,强化学习,招聘HR,开发者生态

nemotron-halloween

HuggingFace Blog
2026-10-30T17:57:24.636Z · 大模型,算力芯片,AI应用,开源,Google,NVIDIA,阿里巴巴,语音音频,Agent智能体,推理思考,搜索RAG,数字人,扩散模型,强化学习,微调蒸馏,模型评测,提示工程,招聘HR
继续滚动加载更多…