The valley of webhooks

Prism
Cursor for hardware engineering
How I use AI (Oct 2026)
MSP-LLM: A Structured Large Language Model Framework for Inorganic Material Synthesis Planning
Reimagining computational quantum research with AI scientists
Beyond Prompt Injection: The Tool Update Gap in LLM Agent Security
Toward Bounding Coding-Agent Autonomy in Software Maintenance: A Pilot Study of Boundary Contracts
Optimize the Harness, Not the Model: Fitting a Minimal Agent to a Self-Hostable LLM for Investigative Analysis
Can We Stop the Backtest Yet? Anytime-Valid Promotion Tests for Adaptive Financial Research Agents
CoworkOS:Scaling Agent Coworkers for Real-world Automation
TLAPS-Bench: Formally Proving Correctness of Real-World System Specifications with TLA+ Proof System
Parametric CAD Bench v3: Evaluating Agentic Parametric CAD Authoring from Text and Engineering Drawings
Skill++: Towards Lifelong Agents via Routing-Aware Skill Refinement
Exo: An Architecture for Self-Improving Systems at Runtime
Decentralized Multi-Agent Coordination and Communication in Shared Codebases
OpenAI Introduces Pando: A Git Backend That Cuts Median Push Latency ~80%
OpenAI has introduced Pando, a new Git backend that now serves all development in its monorepo. The OpenAI Pando Git backend keeps the standard Git client and protocol. Engineers and Codex agents still run git push and git fetch as before. Only the server changed. OpenAI team reports median push latency fell nearly 80%. Pando now delivers nearly a petabyte of Git data per day.
TL;DR
- Scale: Nearly 1 PB of Git data per day; peak above 57 TB in 1 hour.
- Runs on: Commodity hardware; standard cloud VMs saturate 10 Gbps links on clone and fetch.
- Performance: Thousands of concurrent pushers without degradation, per OpenAI’s own testing.
- Best: Median push latency down nearly 80% (about 5x).
- Worst: Not open source; repeat branch pushes resend non-trunk history (p99 pack under 3 MiB).
What is OpenAI Pando?
Pando is a Git-compatible server backend from OpenAI that scales concurrent pushes and fetches for a monorepo. It was written in Rust and reached production in 10 weeks. One engineer designed the core and teams of Codex agents implemented it. It has served production traffic since April 2026.
Why did OpenAI need a new Git backend?
Codex multiplied parallel work. OpenAI’s commit chart shows commits landed on master up 1,378% in Q3 2026 versus Q1 2024. Its Q4 2026 estimate is +2,442%. Each push now triggers many CI fetches. By late 2025, fetches and pushes slowed, merges failed, and reliability at times fell below 90%. OpenAI concluded the bottleneck was how it served Git, not Git itself.
How does Pando work?
Pando drops 2 assumptions that most Git servers treat as requirements:
1. Repository-wide consistency: Conventional servers order every ref update repo-wide, so unrelated pushes wait. Pando uses causal consistency instead. Each branch is serialized on its own, and clients only conflict when pushing the same ref. The tradeoff: a reader viewing several branches may see them at different points in time.
2. A unique packfile per client: Standard servers build a fresh pack per fetch. Pando stores each pushed pack as an immutable blob. A “ref version” goes into a scalable metadata store. A push needs O(1) metadata reads and writes. A fetch needs O(log Δ) reads, where Δ is the ref-version gap to close.
How are pushes kept small and reusable?
With millions of branches, a full ref advertisement can exceed 100 MiB. Pando advertises only the trunk branch as the base for new feature-branch pushes. Any reader with trunk history can then fetch that branch from 1 stored pack. In OpenAI’s monorepo, the median pack was under 20 KiB.
How are fetches served at line rate?
Pando returns download links via packfile-uri, an existing Git protocol feature. It sends an empty inline pack. A delivery service called Express caches packs regionally, using consistent hashing, with hit rates above 99%.
What replaces garbage collection?
Each push creates an “L0” pack. Background workers group packs into geometrically larger covers, similar to LSM-tree compaction. The monorepo currently uses covers up to L4. Covers act as a skip list, so pack selection runs in logarithmic time.
What are the production numbers?
All figures below are self-reported by OpenAI.
- Median push latency reduced by nearly 80%.
- Nearly 1 PB of Git data per day, using only a handful of CPU cores.
- Over 57 TB of packs served in a single hour, more than 99% from local disk cache.
- Clones and fetches saturate 10 Gbps links on standard cloud VMs.
OpenAI also ran a 1,000-writer simulation against 3-phase-commit and write-ahead-log designs. It labels these teaching models, not benchmarks.
How does Pando compare with other approaches?
| OpenAI Pando | GitHub Spokes | Anthropic Scion | |
|---|---|---|---|
| Git client compatible | Yes | Yes | No, own scn client |
| Write coordination | Per-branch, causal consistency | Three-phase commit with quorum | Server-side commits; refs via compare-and-swap |
| Default replicas | Not disclosed (blob + metadata stores) | 5 full copies | No fully materialized repo copy |
| Read path | Reused packs via packfile-uri, Express cache | Closest in-sync replica | Tiered tree/blob caches |
| Cache hit rate | Over 99% | Not disclosed | Over 99% per tier |
| Headline result | Median push latency down ~80% | Serves ~1 billion repositories | 200x smaller CPU/memory footprint |
| Build effort | 10 weeks, Rust | Not disclosed | 7 people, 5 months |
| Available to others | No | Yes, powers GitHub | No |
How was Pando built and deployed?
OpenAI wrote a Git conformance suite for agents and added deterministic simulation testing. Agents using GPT-6 Astra wrote Lean and TLA+ specs to find bugs.
Pando first ran as a read- and write-through proxy, so traffic moved without downtime. OpenAI ships its own Git build to developer machines and the ChatGPT desktop app.
Heimstaden is changing residential real estate management with AI
Accelerating engineering for the physical world

It’s not just Sam Altman: AI will ruin PC gaming in ways you don’t expect
Good lord, it’s been a bad week for gaming. You don’t need to be a news hound or a Nostradamus to see where the problems are coming from: AI. From hardware to software to platforms to funding, “AI” is causing nothing but headaches for most gamers, and anyone else connected to the industry.
Welcome to the Boost Mode newsletter. Every week I share my insights on PC gaming, desktop setups, and hardware optimization. I also track down some of the most interesting PC and nerd news from around the web, plus a PC game pick you might not have seen elsewhere. Want this newsletter to come directly to your inbox? Sign up on our website!
The billionaires want your RAM
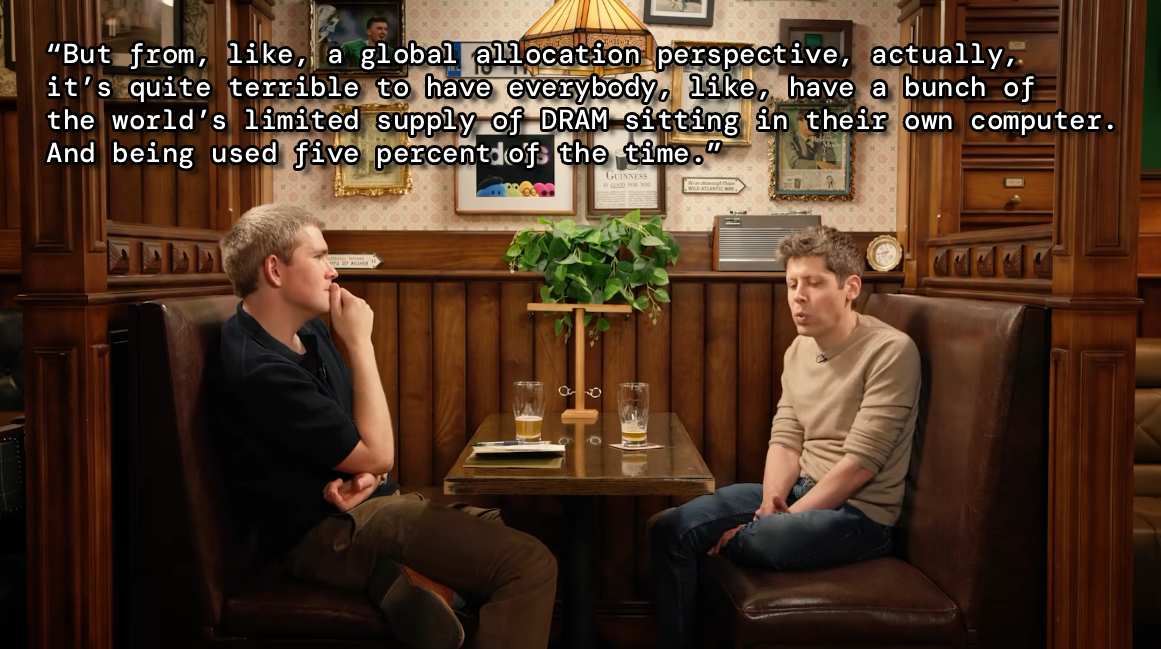
Over a couple of cheeky pints with a fellow CEO, ChatGPT’s chief Sam Altman said the quiet part out loud: Your computer’s RAM would be far better utilized in one of OpenAI’s data centers. He was talking specifically about running AI models — which is possible to do on local hardware, especially on newer designs like Nvidia’s RTX Spark chips — but the sentiment follows for gaming PCs and consoles, too.
From Altman’s perspective as a billionaire profiting off the AI boom, yeah, of course all that hardware would be better in his hands, rented back to corporations and consumers one token at a time. The sentiment comes off as unimaginably elitist, even if it makes cold, robotic sense for pure allocation. One of the richest people on the planet thinks he should have powerful hardware, not you.
And that sure seems to be the way the market is trending, with RAM in laptops and phones going backward for the first time in recent memory, even as every new device crows about AI capability. Remember that big push Microsoft had for “Copilot+” laptops that met a minimum spec, a minimum that its latest (and still very expensive) Surface devices can’t even meet?
It’s kind of ironic that Microsoft is having so much trouble with its Xbox platform. The cheapest Xbox is now $500, and the next-gen “Helix” model is projected to cost $1,200 to $1,800 to produce. Microsoft has been struggling to keep Xbox competitive for over a decade, but it’s hard to feel bad for the company that’s also pushing AI in every one of its products, so much that it had to apologize to Windows users.
Pity Sony and Nintendo, at least theoretically, as their price increases are beyond their control. Pity Framework and Valve for trying to make cool hardware at the worst time imaginable. But don’t shed a tear for Microsoft — it has sewn the wind.
AI slop floods the game platforms
CEOs being out-of-touch elitists isn’t new (here I’ll mention Epic CEO Tim Sweeney for a very specific reason), and we’ve been dealing with a nightmare of hardware prices for a year or so. But Steam’s recent Next Fest event highlighted how the AI problem is affecting the software side, too.
Next Fest has become a calendar event for gamers, a time when developers and publishers release demos for their exciting upcoming titles. But this year, with Steam absolutely infested with AI slop, things felt a little different. Though there was plenty of new stuff to try for PC gamers. But some developers are now wary of publishing demos, for fear that their games will be used as templates for vibe-coded copycats.
The fears are not unfounded. While shovelware and clones have always been a part of the gaming market, being able to point an LLM at an existing game is a new problem. It’s not as if you’re just slapping the cover into a Xerox machine and getting an instant, perfect copy…but it’s not so far removed from that, either. Fraudulent copies of games have already appeared on Steam and other platforms, and developers have been sent extortion messages threatening to use AI to copy their games if they don’t pay up. The problem is so widespread that Anthropic added more stringent, game-specific copyright protections to its Claude LLM.
I didn't filter, this is just "recently added"
— Kenney (@kenney.nl) 2026-11-01T09:36:34.926Z
Steam has moderation tools to stop outright fraud and intentional customer confusion. And Steam, more than other platforms, has at least made token attempts to inform players when generative AI is being used. But Valve has stopped short of allowing end users to filter out projects that are partly or mostly built with generative AI.
Valve is either unwilling or unable to be the slop police. It’s trying to walk a fine line between quality control and developer freedom. On one side, you get a walled garden that’s inaccessi